 ModelFold
google/gemini-3-1-flash-tts
Gemini 3.1 Flash TTS Preview is an expressive text-to-speech model by Google that delivers natural AI voice generation with advanced control over tone, emotion, pacing, and speaking style.
Pricing: Billed by length: 9 credits per 1,000 characters (partial thousands round up), minimum 8 credits. Chinese, Japanese and Korean characters count as 3 each when estimating.
Explore more Text to Speech models
More AI models from Google
Latest and popular AI models
Gemini 3.1 Flash TTS API for Natural and Expressive Voice Generation
Create expressive AI speech with Gemini 3.1 Flash TTS API on ModelFold, featuring natural voices, multilingual generation, and flexible control over audio delivery.
Meet Gemini 3.1 Flash TTS for More Expressive AI Speech
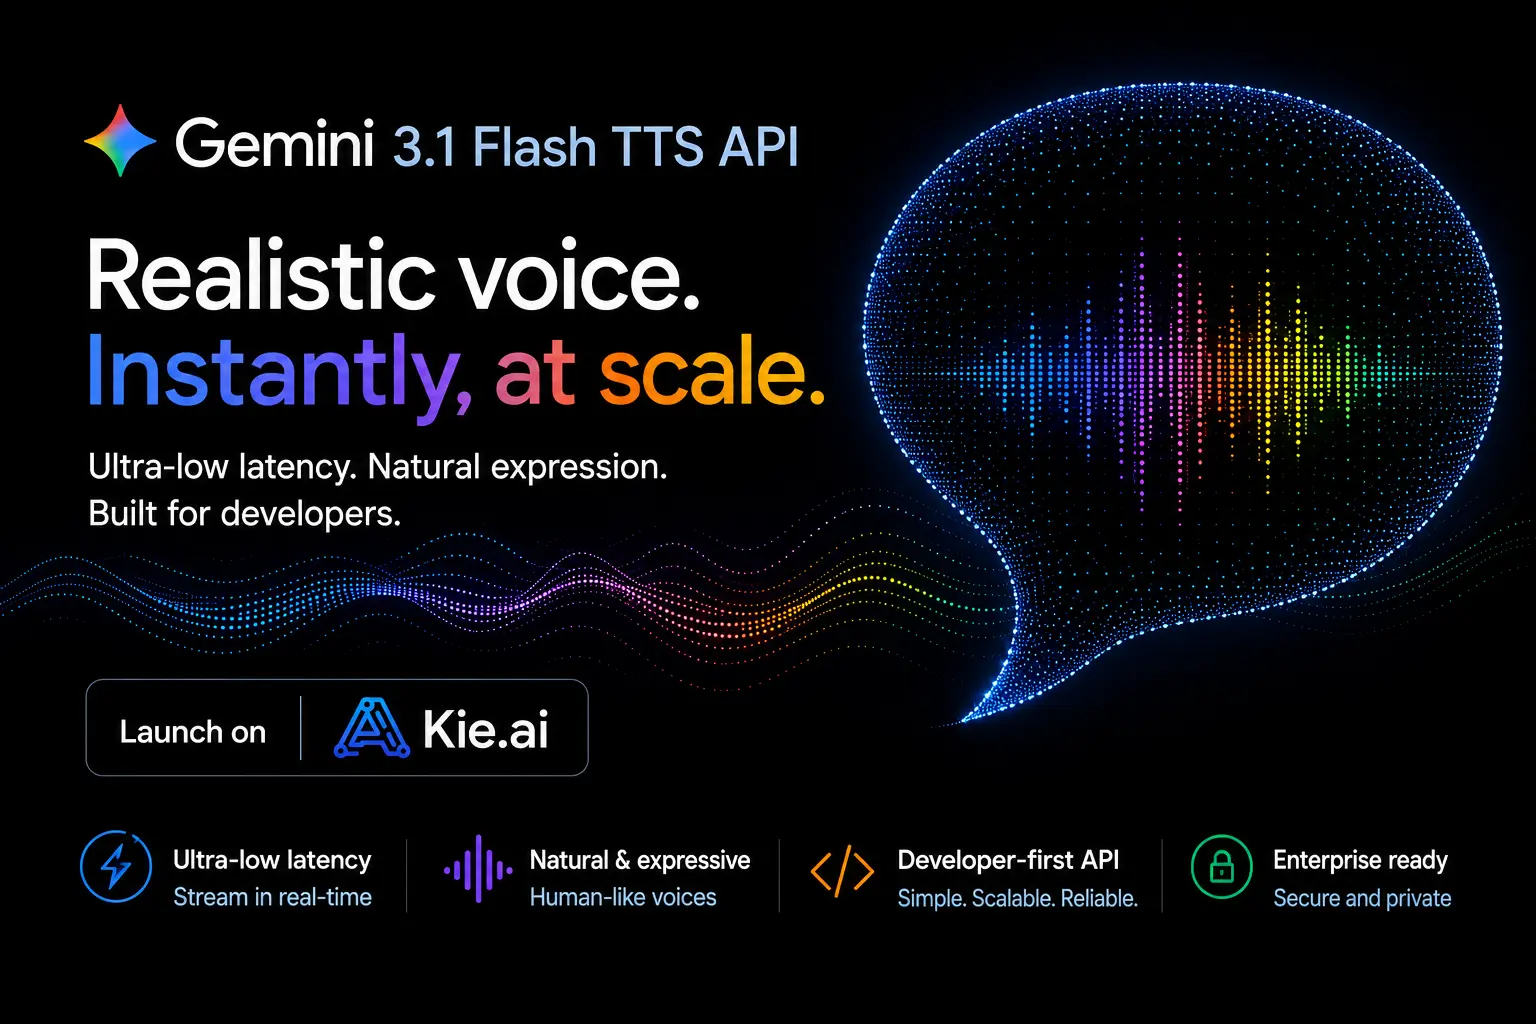
Gemini 3.1 Flash TTS is Google’s expressive text-to-speech system for transforming written content into natural, high-fidelity audio with precise control over vocal delivery. It supports more than 70 languages, a broad selection of prebuilt voices, and multi-speaker dialogue, while natural-language instructions and 200+ inline audio tags can shape tone, emotion, pacing, pauses, accents, and mid-sentence transitions. Developers can integrate these controllable speech-generation capabilities into their applications through the Gemini 3.1 Flash TTS API on ModelFold.
What Makes Gemini 3.1 Flash TTS Preview API More Powerful Than Gemini 2.5 Flash TTS API
Compared with Gemini 2.5 Flash TTS, Gemini 3.1 Flash Preview TTS introduces stronger speech quality, more detailed expression control, wider language support, and more flexible voice direction capabilities. The improvements focus on making AI-generated speech more natural, more customizable, and better suited for complex audio experiences, from realistic narration to multi-speaker interactions. All supported features, voice options, and integration details should be confirmed through the latest ModelFold API documentation.
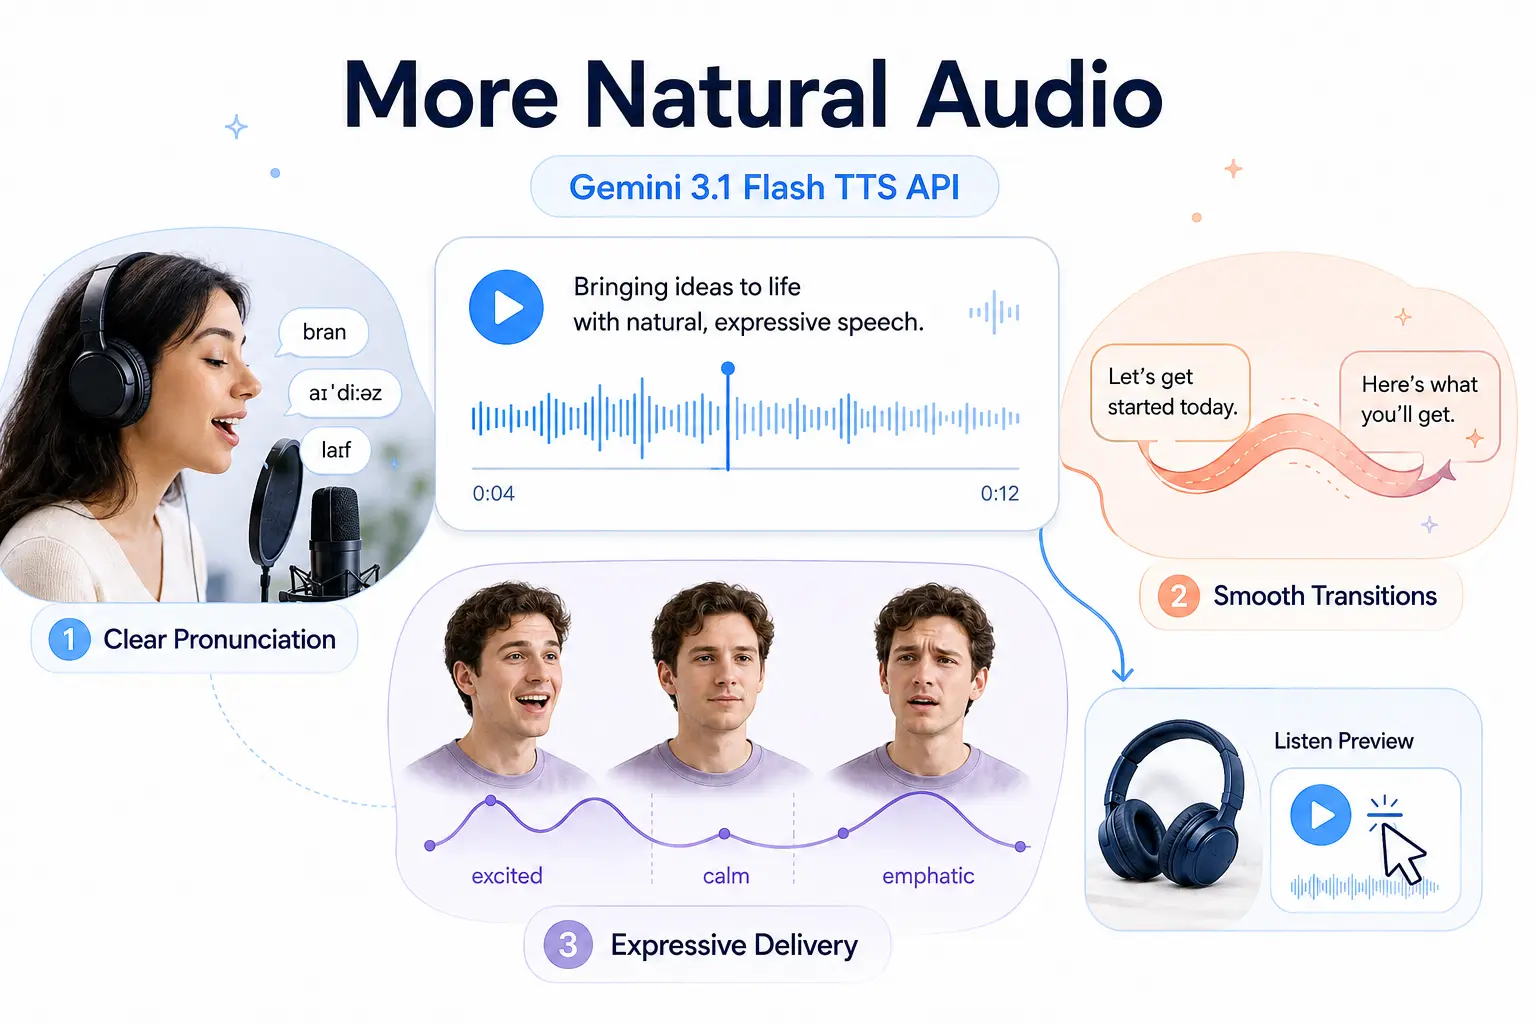
Generate More Natural Audio with Gemini 3.1 Flash TTS API
Improved speech generation quality allows Gemini 3.1 Flash TTS API to produce clearer pronunciation, smoother transitions, and more expressive vocal delivery. The enhanced audio output can better follow the context and intention of written content, helping developers create more realistic narration, conversational voices, and interactive speech experiences.
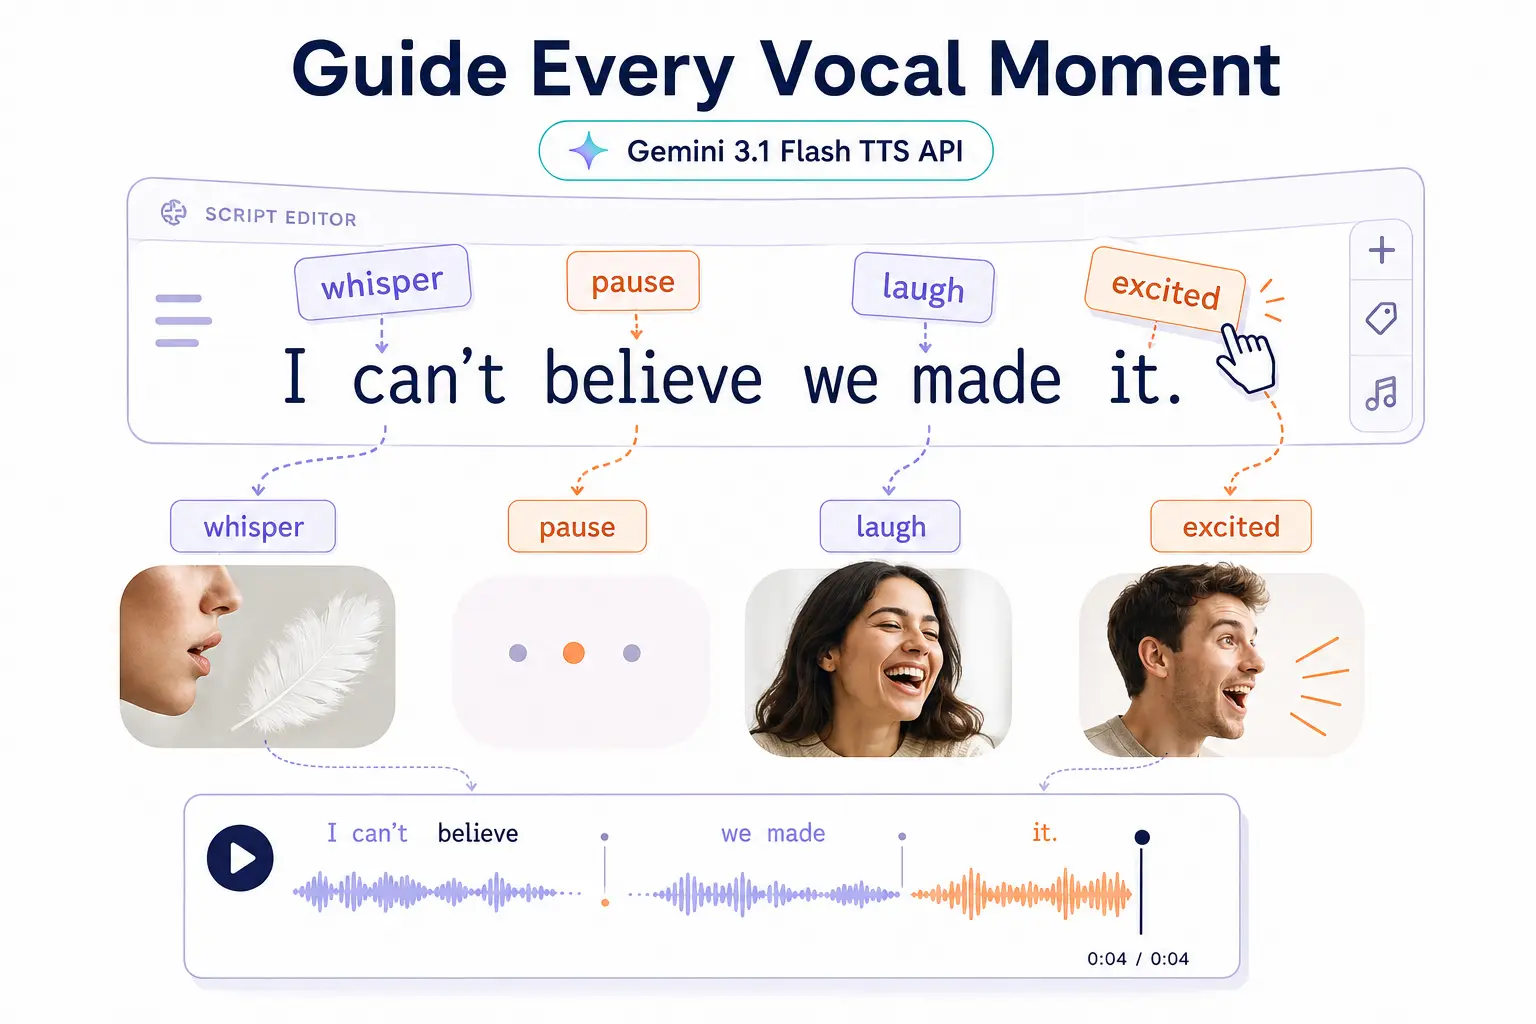
Control Voice Delivery with Audio Tags in Gemini 3.1 Flash TTS API
Audio tags provide developers with a more detailed way to guide speech performance by adjusting emotions, pacing, pauses, whispers, laughter, and other vocal elements. With these controls available in Gemini 3.1 Flash TTS API, generated voices can shift naturally throughout a script instead of maintaining a single fixed delivery style.
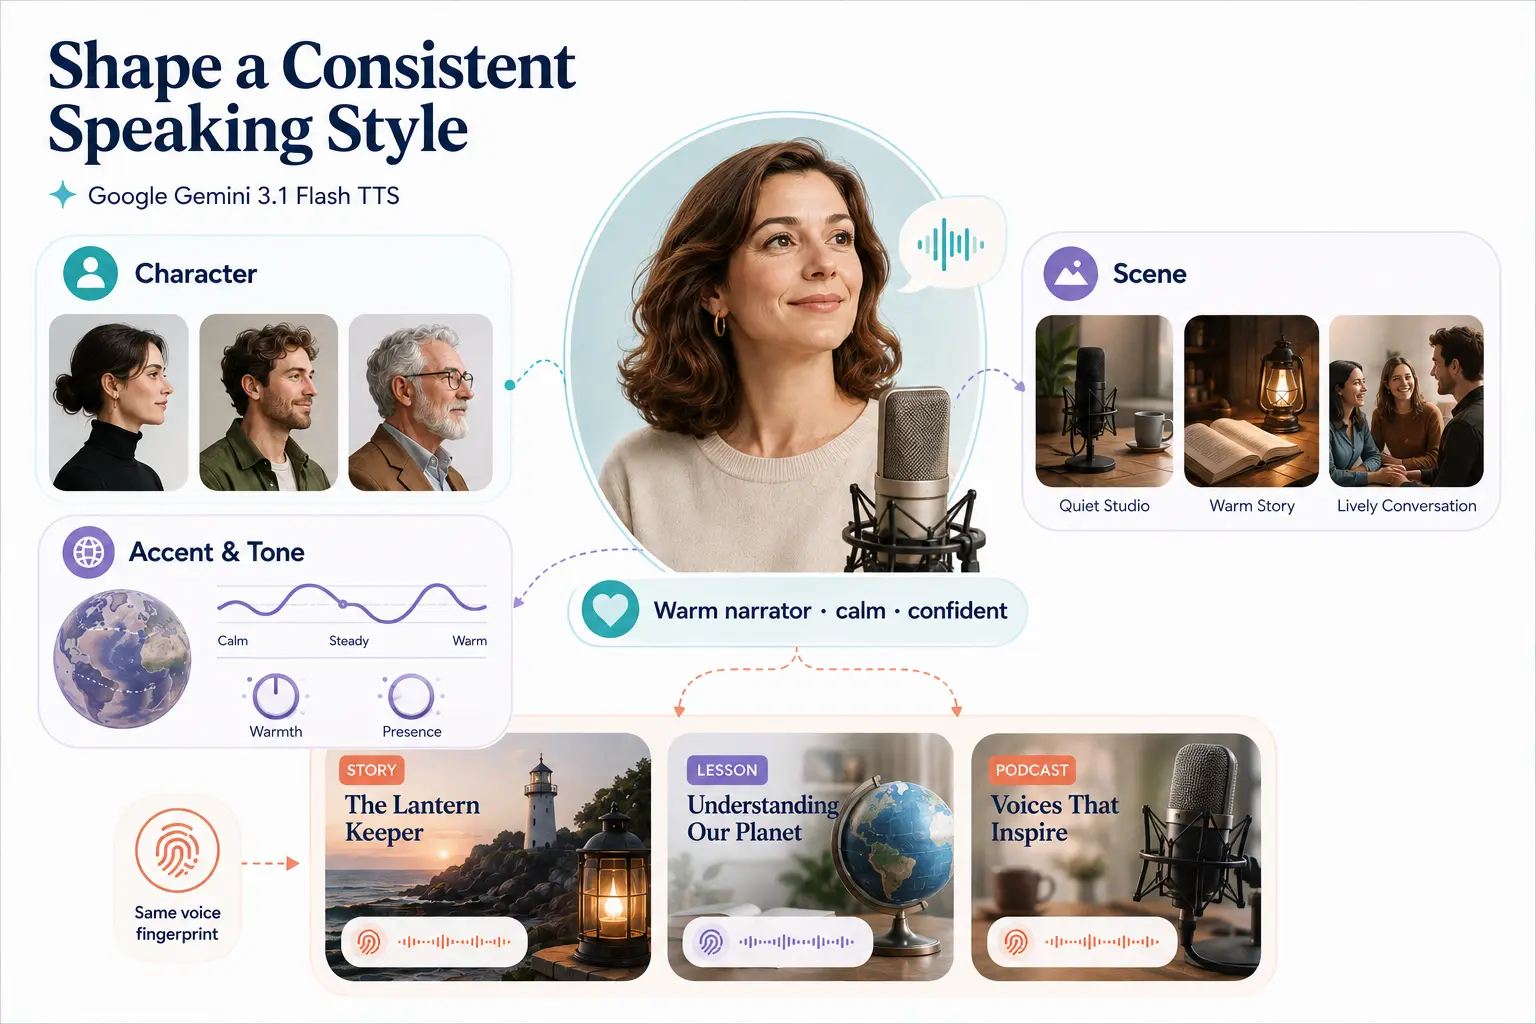
Shape Custom Speaking Styles Through Google Gemini 3.1 Flash TTS API
Natural-language voice direction gives creators more flexibility when designing specific speaking styles, including character identity, scene atmosphere, accent preferences, and overall tone. Through Google Gemini 3.1 Flash TTS API, these instructions can help maintain consistent voice characteristics across different audio projects.
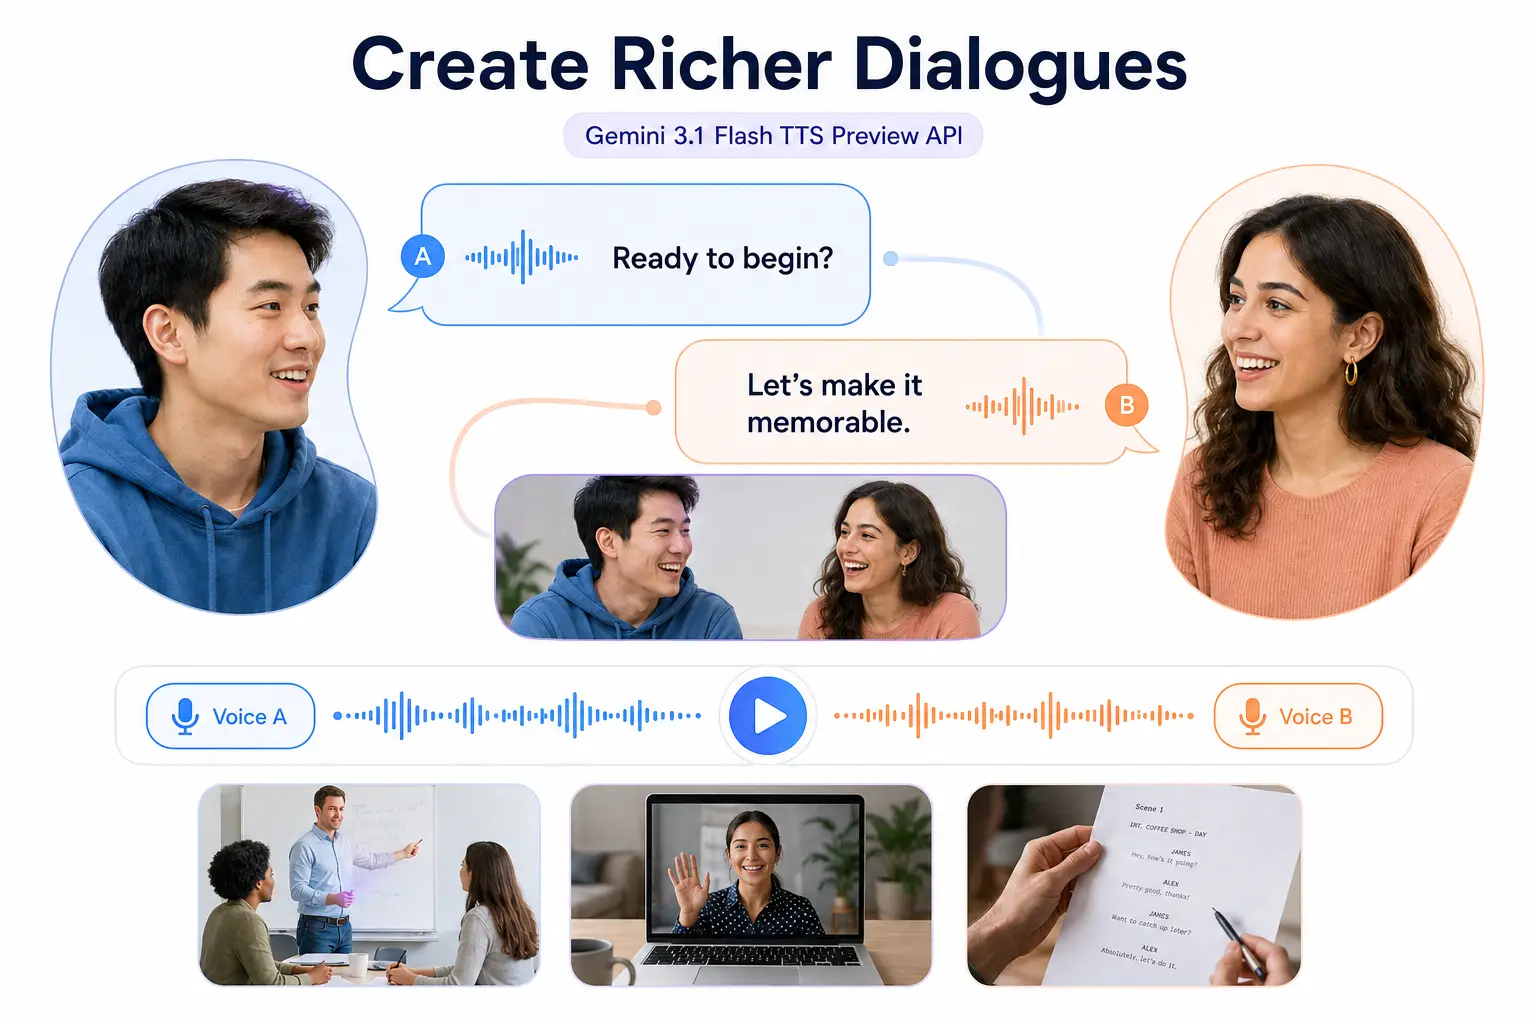
Create Richer Dialogues with Gemini 3.1 Flash TTS Preview API
Multi-speaker generation expands the possibilities for dialogue-based audio content by allowing different voices and styles to work together in one output. Gemini 3.1 Flash TTS Preview API supports more engaging conversations for virtual characters, educational materials, scripted discussions, and other interactive scenarios.
Deliver Multilingual Experiences with Gemini 3.1 Flash text To Speech API
Supporting more than 70 languages enables developers to create localized speech experiences for audiences across different regions. Gemini 3.1 Flash text To Speech API combines broad language coverage with expressive voice control, making multilingual audio generation more natural and adaptable. Check the latest ModelFold API documentation for current language availability, supported voices, and feature updates.
Build Flexible Speech Applications with gemini-3.1-flash-tts-preview API
From audiobooks and podcasts to learning platforms and interactive applications, flexible speech generation helps developers adapt AI voices to different content formats. The gemini-3.1-flash-tts-preview API allows teams to combine voice selection, style instructions, and expressive controls when creating customized audio experiences.
How Does Gemini 3.1 Flash TTS Stand Out Among Leading Text-to-Speech Models
Gemini 3.1 Flash TTS focuses on balancing high-quality speech generation with detailed control over expression, pacing, and voice direction. Compared with other advanced text-to-speech models, it emphasizes natural conversational delivery, multilingual speech generation, and flexible control over how audio content is performed. The following comparison highlights key differences across major AI speech models.
| Comparison Area | Gemini 3.1 Flash TTS | Gemini 2.5 Flash TTS | Eleven v3 | Inworld TTS |
|---|---|---|---|---|
| Model Positioning | Expressive speech generation model designed for natural delivery, detailed control, and scalable multilingual audio creation | Earlier Gemini TTS model focused on efficient and general speech synthesis | Advanced voice generation model focused on highly expressive and realistic speech | Character-focused speech model designed for interactive AI experiences |
| Speech Naturalness | Strong naturalness with improved vocal clarity, conversational rhythm, and expressive variation | Provides natural speech output with less refined delivery control | High-quality voice realism with strong emotional performance | Natural character-style voices optimized for interactive scenarios |
| Expressive Control | Audio tags and natural-language instructions provide detailed control over emotion, pacing, pauses, and vocal style | Supports general voice instructions with fewer fine-grained controls | Provides voice style and emotional control through prompting and voice design | Emphasizes personality-driven voice customization |
| Voice Direction | Supports speaker identity, scene context, accent, tone, and performance guidance | Provides basic style guidance for speech generation | Allows detailed voice and character direction | Designed around creating unique AI characters and personalities |
| Multilingual Capability | Supports more than 70 languages with multilingual speech generation | Supports multilingual output with broader limitations compared with newer generation capabilities | Supports multilingual voice generation across different regions | Provides multilingual capabilities for conversational applications |
| Multi-Speaker Dialogue | Supports multiple speakers with separate voice characteristics and delivery styles | Provides more limited dialogue generation capabilities | Supports multi-voice creation depending on workflow | Strong focus on character interaction and dialogue scenarios |
| Speech Customization | Enables both global style direction and moment-level delivery adjustments | Mainly focused on overall voice generation settings | Strong customization through voice design and style control | Strong customization for interactive characters |
How to Create Expressive Speech with Gemini 3.1 Flash TTS Preview API
Get started with our product in just a few simple steps...
- 1
1. Create an Account and Get Your Gemini 3.1 Flash TTS Preview API Key
Start by creating a ModelFold account and obtaining your API key for accessing Gemini 3.1 Flash TTS Preview API. Gemini 3.1 Flash TTS Preview API Key connects your application with the speech generation service and allows developers to manage requests through a unified API workflow.
- 2
2. Configure Gemini 3.1 Flash TTS Preview API Model Settings
After obtaining access, select Gemini 3.1 Flash TTS Preview API and configure the required speech generation settings. Developers can define text input, voice preferences, language options, and style instructions to prepare the request for generating customized audio output.
- 3
3. Send Speech Generation Requests with Gemini 3.1 Flash TTS Preview API
Once the configuration is completed, send a POST request to https://ai.modelfold.online/v1/audio/generations with "model": "google/gemini-3-1-flash-tts", the text in prompt (one line per turn, "Speaker 1: …" / "Speaker 2: …", for dialogue), voice / voice_2 and optional style, scene and sample_context. The response returns the finished audio URL.
- 4
4. Customize Voice Output with Gemini 3.1 Flash TTS Preview API Features
Using available speech controls, developers can refine generated audio by adjusting expressive elements such as emotions, pauses, speaking style, and character direction. These customization options help create more natural narration, dialogue, and interactive voice experiences.
- ✓
5. Integrate Generated Audio into Your Applications
After receiving the generated audio response, developers can integrate the output into different products, including voice assistants, audiobooks, podcasts, education platforms, and accessibility solutions. Check the latest ModelFold API documentation for current API parameters, supported features, and integration updates.
Guide to Prompting gemini-3.1-flash-tts-preview API for More Expressive Speech
Follow these helpful tips to get the most out of our platform.
Keep Your Instructions and Text Aligned in Gemini 3.1 Flash TTS API
The strongest results usually come when the intended speaking style matches the content itself. If the prompt asks for urgency, excitement, or tension, the written text should also reflect that feeling so the generated audio sounds more believable and consistent.
Leave Room for Natural Delivery with Gemini 3.1 Flash TTS API
Over-controlling every small detail can make the output feel less fluid. A clear overall direction often works better than trying to force every word, pause, and emotional shift, because Gemini 3.1 Flash TTS can naturally fill in some of the performance detail on its own.
Write Vivid, Speakable Text for Google Gemini 3.1 Flash TTS API
More expressive wording gives the voice more to work with. Sentences that carry emotion, tension, surprise, warmth, or personality usually lead to more engaging audio than flat or overly generic phrasing, especially in narration, dialogue, and storytelling scenarios.
Use Audio Tags for Specific Moments in Gemini 3.1 Flash TTS Preview API
Prompts are useful for shaping the overall speaking style, while audio tags are better for controlling individual moments. This makes it easier to add a pause, soften a phrase, shift the emotion, or create a stronger vocal reaction exactly where it matters in the script.
Let Punctuation Improve Rhythm in Gemini 3.1 Flash text To Speech API
Commas, periods, and other punctuation marks can help shape the natural flow of speech. Well-structured sentences often produce smoother breathing, clearer phrasing, and better pacing, which is especially helpful for long-form audio and explanation-based content.
Test and Refine Delivery Step by Step with gemini-3.1-flash-tts-preview API
Small prompt adjustments can make a noticeable difference in the final voice output. Rather than rewriting everything at once, developers can refine style instructions, emotional wording, and tag placement gradually to reach a more natural and controlled result. Check the latest ModelFold API documentation for current supported features, voices, and prompt-related options.
Where Gemini 3.1 Flash TTS API Can Bring AI Speech to Life
Expressive Audiobooks and Story Narration with Gemini 3.1 Flash TTS API
Audiobook platforms and storytelling applications can use Gemini 3.1 Flash TTS API to transform written stories into expressive narration with more natural pacing and emotional variation. By combining voice direction with speech controls, developers can create immersive listening experiences with distinct character styles, smoother transitions, and more engaging storytelling.
Interactive Voice Assistants Powered by Gemini 3.1 Flash TTS API
Voice assistants and conversational applications can leverage Gemini 3.1 Flash TTS API to generate more natural spoken responses for users. The ability to adjust tone, rhythm, and delivery style helps create voice interactions that feel more adaptive across customer support, virtual assistants, and AI-powered applications.
Multilingual Content Creation Using Gemini 3.1 Flash TTS Preview API
Content platforms targeting global audiences can apply Gemini 3.1 Flash TTS Preview API to generate localized audio experiences across different languages. With support for more than 70 languages and flexible voice control, developers can create multilingual courses, media content, product explanations, and regionalized audio materials.
Accessibility and Enterprise Audio Solutions with Gemini 3.1 Flash TTS Preview API
Accessibility products and business applications can use Gemini 3.1 Flash TTS Preview API to deliver clear and expressive speech output. From screen readers and audio descriptions to automated notifications and customer communication systems, generated voices can be adjusted to match different information delivery requirements.
Why Choose Google Gemini 3.1 Flash TTS API on ModelFold
Cost-Effective Gemini 3.1 Flash TTS API Pricing
ModelFold provides a more accessible way for developers to work with Gemini 3.1 Flash TTS API while maintaining the core speech generation capabilities required for different applications. Flexible pricing options make it easier to test, scale, and integrate AI speech features into projects with different usage requirements.
Simple Integration with Gemini 3.1 Flash TTS API
A streamlined integration workflow helps developers connect Gemini 3.1 Flash TTS API with their applications more efficiently. With clear API access, straightforward request handling, and an organized development process, teams can focus more on building speech-powered experiences instead of managing complex setup procedures.
Complete Gemini 3.1 Flash TTS API Documentation
Detailed documentation helps developers understand available features, request structures, supported options, and integration workflows when building with Gemini 3.1 Flash TTS API. Clear guidance makes it easier to explore voice generation capabilities and implement speech solutions for different application scenarios.
Multiple AI Speech Models Available on ModelFold
ModelFold offers access to multiple AI models, allowing developers to explore different speech generation options and select suitable solutions based on quality, speed, and application requirements. This flexibility helps teams compare capabilities and build audio workflows with the right model choice.
Reliable Support for Gemini 3.1 Flash TTS API Integration
Technical support helps developers resolve integration questions, troubleshoot issues, and improve their speech generation workflows. Whether testing new applications or deploying production projects, assistance is available throughout the development process.
Build Scalable Audio Applications with Gemini 3.1 Flash TTS API
From content creation platforms to voice assistants and accessibility tools, Gemini 3.1 Flash TTS API can support a wide range of AI audio applications. ModelFold provides an environment where developers can experiment with expressive speech generation and expand their audio projects efficiently.
FAQs About Gemini 3.1 Flash TTS API
What Is Gemini 3.1 Flash TTS API?⌄
Gemini 3.1 Flash TTS API is a text-to-speech model designed to transform written content into natural and expressive audio. It supports detailed voice control through style instructions and audio tags, allowing developers to adjust tone, pacing, emotion, and delivery style for different speech generation scenarios.
What Makes Gemini 3.1 Flash TTS Different from Gemini 2.5 Flash TTS?⌄
Compared with Gemini 2.5 Flash TTS, Gemini 3.1 Flash TTS brings stronger speech quality, more detailed expression control through audio tags and natural-language direction, support for more than 70 languages, and more flexible voice direction for multi-speaker dialogue.
How Do Audio Tags Work in Gemini 3.1 Flash TTS?⌄
Audio tags allow developers to guide specific parts of speech output by adding expressive instructions to the text. They can help control elements such as emotions, pauses, whispers, laughter, and pacing changes, making generated audio more dynamic and natural for narration, dialogue, and interactive applications.
Can Gemini 3.1 Flash TTS Generate Multiple Speakers?⌄
Yes. Gemini 3.1 Flash TTS supports multi-speaker dialogue generation with different voice characteristics and delivery styles for each speaker. This capability allows developers to create more natural conversations, character interactions, educational dialogues, and scripted audio experiences with distinct speaker identities. Check the latest ModelFold API documentation for supported multi-speaker configurations, available options, and integration details.
What Types of Applications Can Use Gemini 3.1 Flash TTS API?⌄
Gemini 3.1 Flash TTS API can support a wide range of speech-based applications, including audiobooks, podcasts, voice assistants, accessibility tools, educational platforms, localized content, and automated business communications. Its expressive controls and multilingual capabilities make it suitable for projects that require more engaging AI-generated voices.
Is Gemini 3.1 Flash TTS API Available Through ModelFold?⌄
Yes. Developers can access Gemini 3.1 Flash TTS API through ModelFold and integrate expressive AI speech generation into their applications. ModelFold provides a streamlined way to connect with the model and build speech-powered workflows without managing separate integrations.
Where Can I Find Gemini 3.1 Flash TTS API Documentation?⌄
The latest Gemini 3.1 Flash TTS API documentation on ModelFold provides information about integration methods, supported options, available capabilities, and usage requirements. Developers should review the documentation for updated model features and current API details.
| Gemini 3 1 Flash Tts | 9 credits / 1,000 chars · min 8 |
The estimate is held when the task starts; once it finishes, the charge is settled to the actual upstream usage (refund or top-up), never below the minimum.
curl https://ai.modelfold.online/v1/audio/generations \
  -H "Authorization: Bearer $MODELFOLD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"google/gemini-3-1-flash-tts","prompt":"Speaker 1: Hello!\nSpeaker 2: Hi there.","voice":"Zephyr"}'