 ModelFold
gemini-3-pro
Gemini 3 Pro API is Google DeepMind’s next-generation multimodal model that delivers advanced reasoning, seamless text-image-video-audio understanding, and large-scale long-context processing.
Pricing: Input 125 credits / 1M tokens (≈ $0.63), Output 875 credits / 1M tokens (≈ $4.38).
How can I help you today?
Explore more Chat models
More AI models from Google
Latest and popular AI models
Affordable Gemini 3 API & Gemini 3 Pro API Integration
Access Google's Gemini 3 Pro API via ModelFold to leverage state-of-the-art reasoning and native multimodal capabilities. Start building powerful agentic workflows today with our free testing credits and competitive pricing.
Why Integrate Gemini-3-Pro API into Your Applications?
Unprecedented Reasoning and Multimodal Understanding via Gemini 3 API
Gemini 3 API delivers state-of-the-art reasoning, solving complex, nuanced problems at a PhD level. Gemini 3 Pro API is natively multimodal, seamlessly processing and synthesizing inputs from text, images, video, and audio simultaneously for true, real-world comprehension.
Elevate Agentic Capabilities and Long-Horizon Planning with Gemini 3 Pro
Achieve reliable automation. Gemini 3 Pro API excels at agentic coding and managing multi-step, long-horizon workflows consistently. Integrate Gemini 3 API to delegate sophisticated tasks, maximizing efficiency and minimizing errors in complex sequences.
Advanced Vibe Coding and Developer Productivity with Google Gemini 3 API
Accelerate development with powerful zero-shot generation. Google Gemini 3 API simplifies "vibe coding," transforming complex creative prompts directly into highly responsive web UIs and functional code. This capability dramatically boosts developer productivity and app quality.
Gemini 3 Pro API Features & Specifications
State-of-the-Art Reasoning Powers of Google's Gemini 3 Pro API
Gemini 3 Pro API is widely referred to as Google's "most intelligent model," featuring deeper, more nuanced reasoning capabilities. It sets new benchmarks in advanced problem-solving, significantly outperforming competitors in critical tests like the Humanity’s Last Exam. This ensures your applications benefit from the highest degree of intelligence and reliability for complex tasks.
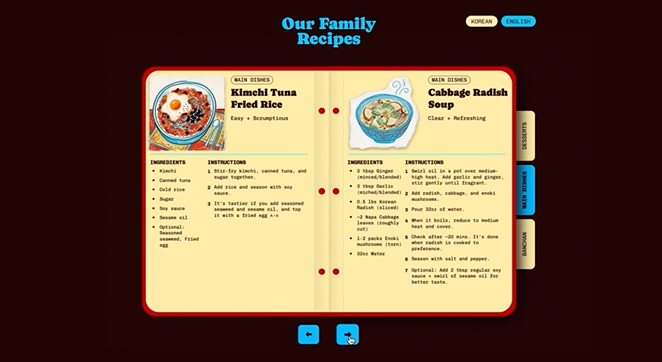
Deeper Understanding of Text, Images, Files & Video via Gemini 3.0 API
Gemini 3.0 API is natively multimodal, seamlessly integrating information from diverse inputs: Text, Images, Video, Audio, PDFs, and entire code repositories. This capability goes beyond simple recognition; it fuses and reasons across these different data types simultaneously, allowing for innovative application development with Gemini 3 API.
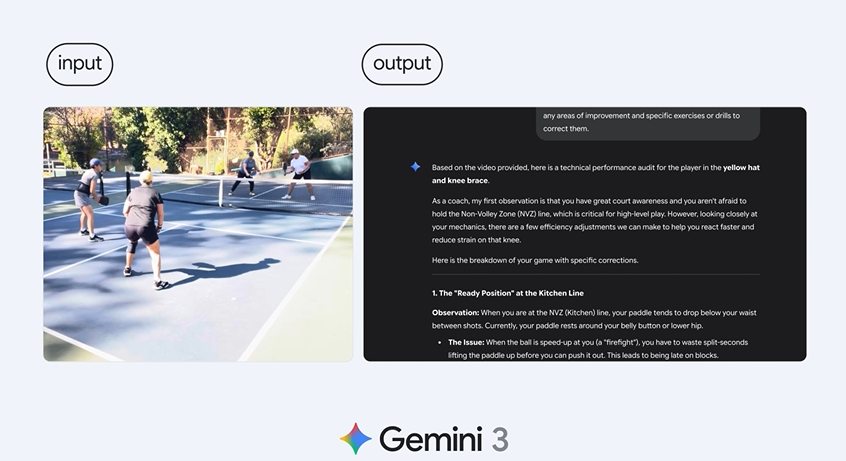
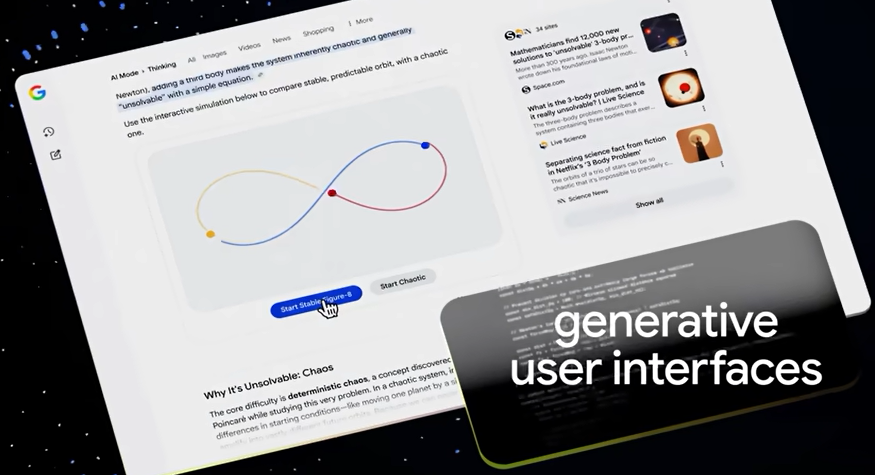
High-Fidelity Visualizations and Richer Interactivity with Gemini 3 API
Transform abstract concepts into stunning visuals. Gemini 3 Pro API generates code for high-fidelity visualizations, complex 3D voxel art, and interactive web experiences from simple prompts. This capability allows developers to render richer, dynamic interfaces that far surpass previous static generation limits.
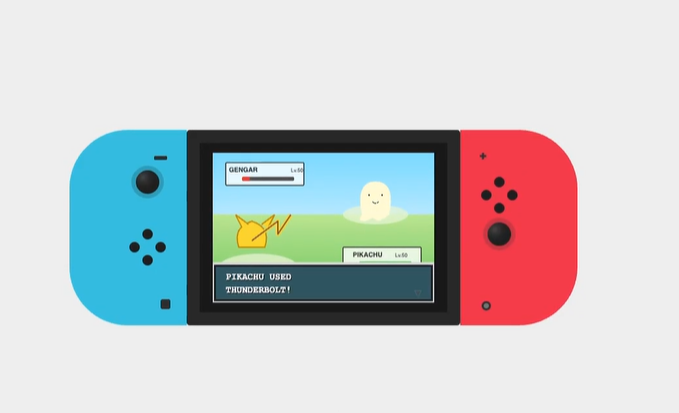
Advanced Agentic Coding and Tool Execution using Gemini3 API
Harness power of agentic coding. Gemini 3 Pro excels at handling complex instructions, performing zero-shot code generation, and executing tool calls reliably. Utilizing gemini3 pro api allows developers to build autonomous systems that plan, code, and validate their actions within end-to-end workflows.
What is Gemini 3 Deep Think Mode?
PhD-Level Reasoning Powered by Gemini 3 Pro API
Gemini 3 Deep Think mode is the highest-intelligence setting of the gemini 3 api, built on Google’s Gemini 3 Pro API, using parallel thinking and reinforcement learning to deliver deeper, more accurate reasoning. Compared with standard gemini-3-pro api outputs, it produces more reliable results for complex math, science, and logical problems.
Built for High-Stakes Applications on the Gemini API
Deep Think turns gemini3 api into a true reasoning engine for financial analysis, legal review, research, and autonomous agents. By prioritizing correctness over speed, gemini3 pro api becomes ideal for mission-critical workflows where a single wrong step can break the entire result.
How Deep Think Works Inside Gemini 3.0
When enabled, the gemini api runs long-horizon reasoning loops inside Gemini 3 Pro API, allowing the model to plan, test, and validate answers before responding. Combined with Gemini 3’s unified multimodal architecture, Gemini 3.0 API can reason across text, images, video, audio, and code in one coherent thinking process.
Getting Started: Free Access to Gemini 3 Pro API and Affordable Pricing
- 1
Free Tier & Trial Credits: Test the Gemini 3 API Risk-Free
We want you to experience the power of the Gemini3 API firsthand. Sign up today to receive a generous allocation of free credits. This allows you to explore the multimodal, agentic, and reasoning capabilities of Gemini 3 Pro on ModelFold without any upfront commitment. Start coding, prototyping, and testing your application ideas immediately.
- 2
Seamless API Integration with the Gemini API
Integrating Gemini API through ModelFold is fast and developer-friendly. We provide comprehensive documentation, quickstart guides, and SDKs to ensure a smooth connection. Access the raw power of Gemini 3 Pro with minimal latency and maximal stability, allowing you to focus purely on innovation.
- ✓
Unbeatable Pricing for the Same High-Performance Gemini 3 Pro Models
ModelFold offers incredibly competitive pricing, ensuring you get access to the exact same Google Gemini 3 models—not the free or limited versions—at an affordable price. Our platform prioritizes cost-effectiveness, making the full capabilities of Gemini 3 Pro API accessible to startups and large enterprises alike, dramatically lowering your overall AI operating costs.
Gemini 3 Benchmarks and Leading Scores
Gemini 3 API sets new state-of-the-art records across major AI evaluations. This data confirms Gemini 3 Pro API's superiority in complex reasoning, multimodal understanding, and agentic coding, making it the most powerful model for your applications.
| Feature Area | Benchmark / Metric | Gemini 3 Pro Score | Key Developer Insight |
|---|---|---|---|
| Academic Reasoning | Humanity’s Last Exam | 37.5% | Demonstrates PhD-level reasoning and reliability on complex problems. |
| Scientific Knowledge | GPQA Diamond (No Tools) | 91.9% | Industry-leading factual accuracy for technical and research tasks. |
| Multimodal Fusion | MMMU-Pro (Multimodal Reasoning) | 81.0% | World-leading ability to analyze and synthesize diverse inputs (image + text). |
| Video Understanding | Video-MMMU (Knowledge Acquisition) | 87.6% | Exceptional comprehension of real-world video data and temporal context. |
| Agentic Coding | Terminal-Bench 2.0 (Tool Use) | 54.2% | Superior execution and validation for autonomous coding workflows. |
| Long-Context Reasoning | MRCR v2 (1M-token needle test) | 26.3% | Efficient retrieval and reasoning within massive 1-million-token context windows. |
| Competitive Coding | LiveCodeBench Pro (Elo Rating) | 2,439 | Highest score for producing accurate, high-quality code under constraints. |
| Long-Horizon Planning | Vending-Bench 2 (Net Worth) | $5,478.16 | Sustained strategic decision-making over multi-step workflows using gemini 3 api. |
Gemini 3 vs. GPT-5.1 Performance
In a head-to-head benchmark comparison, Gemini 3 Pro achieved ~37.5% on the Humanity’s Last Exam reasoning benchmark, significantly ahead of GPT 5.1’s ~26.5%. This measurable advantage indicates that when tackling deep, academic-style thinking tasks, the Gemini 3 API holds a clear lead, ensuring higher accuracy for complex analytical workflows.
| Metric / Benchmark | Gemini 3 Pro Score | GPT-5.1 Score | Performance Gain |
|---|---|---|---|
| Reasoning (Humanity’s Last Exam) | 37.5% | 26.5% | ~41% higher accuracy in complex, PhD-level problem solving. |
| Agentic Coding (Terminal-Bench 2.0) | 54.2% | 47.6% | Superior reliability in executing autonomous coding tasks. |
| Long-Horizon Planning (Vending-Bench 2) | $5,478.16 | $1,473.43 | 3.7× higher value generation for extended agentic workflows. |
| Multimodal Understanding (MMMU-Pro) | 81.0% | 76.0% | Leading ability to synthesize text, image, and video inputs. |
| Context Window | 1M Tokens | Not Publicly Listed | Massive context for processing enterprise-scale datasets. |
Gemini 3 vs. Claude 4.5 Performance
Compared to Claude Sonnet 4.5, Gemini 3 Pro delivered ~$5,478 mean net-worth on agent-simulation benchmarks versus ~$3,838 for Claude. This showcases the stronger performance of Gemini 3 Pro API in long-horizon planning and execution tasks. While competitors offer established ecosystems, Gemini 3 via ModelFold is positioned for high-end reasoning and state-of-the-art multimodal strengths.
| Metric / Benchmark | Gemini 3 Pro Score | Claude Sonnet 4.5 | Performance Gain |
|---|---|---|---|
| Context Window | 1M Tokens | 200K Tokens | 5× larger context capacity for analyzing massive documents or codebases. |
| Reasoning (Humanity’s Last Exam) | 37.5% | 13.7% | Drastically better performance on difficult, nuance-heavy cognitive tasks. |
| Multimodal Understanding (MMMU-Pro) | 81.0% | 68.0% | Superior accuracy in cross-modal (image/text/video) reasoning. |
| Long-Horizon Planning (Vending-Bench 2) | $5,478.16 | $3,838.74 | More consistent and profitable decision-making over time. |
Powerful Gemini 3 API Use Cases for Developers
Hyper-Efficient Agentic Workflow Automation via Gemini3 Pro API
Utilize Gemini3 Pro API’s superior agentic capabilities for complex automation. Developers can build autonomous assistants that execute multi-step tasks across external tools, manage large-scale data processing, or handle long-horizon planning. The consistent tool use and deep reasoning make it ideal for dependable enterprise automation.
Vibe Coding and Instant UI Generation with Gemini 3 Pro Coding
Accelerate front-end development using Gemini 3 Pro coding capabilities. The model masters Vibe Coding, transforming ambiguous prompts, sketches, or complex instructions into functional, interactive web UIs and code snippets instantly. This capability drastically reduces development cycles and allows designers and developers to collaborate more fluidly.
Next-Gen Multimodal Content Creation using Gemini 3.0 API
Go beyond simple text generation. Gemini 3.0 API allows for deep multimodal fusion, enabling applications to analyze video content, interpret image inputs, and generate accompanying code or detailed descriptions. Use the Google's Gemini 3 Pro API to create adaptive learning platforms, comprehensive visual search tools, or automated content summarization engines.
Advanced Scientific and Financial Analysis with the gemini-3-pro API
Tap into the model's PhD-level reasoning for high-stakes analysis. The vast 1M context window and high accuracy make the gemini-3-pro API perfect for analyzing extensive research papers, complex legal documents, or large financial reports. Developers can build tools for expert-level knowledge extraction and algorithmic development.
Frequently Asked Questions
How does Gemini 3 Pro API improve upon Gemini 2.5 Pro?⌄
Gemini 3 Pro API improves upon Gemini 2.5 Pro by delivering significantly stronger reasoning, expanded multimodal capabilities (images, video, audio + text), and a much larger context window.
How can I try Gemini 3 Pro API for free?⌄
You can try the gemini 3 pro api for free on ModelFold with trial credits. Just create an account, get your API key, and start using the gemini api.
How does Google's Gemini 3 Pro API compare to GPT-5.1?⌄
Benchmarks show Google's Gemini 3 Pro API outperforms GPT-5.1 in critical areas, achieving ~37.5% on the Humanity’s Last Exam (vs 26.5%) and offering superior agentic planning capabilities. Additionally, its native multimodal fusion is rated significantly higher for complex video and image analysis.
How can I integrate the gemini-3-pro API into my application?⌄
Integration is simple and developer-friendly. ModelFold provides clear documentation to help you get started. You can access the gemini-3-pro API using an API key from ModelFold, making it easy to use the model in your own application.
Can Gemini 3 API handle video and audio inputs directly?⌄
As a natively multimodal model, Gemini 3 Pro can reason over video, audio and images together with text. The ModelFold API currently accepts text messages; check the latest API documentation for supported input formats.
What is Gemini 3 Deep Think mode?⌄
Gemini 3 Deep Think is an enhanced reasoning mode that outperforms the standard Pro model on complex benchmarks like GPQA Diamond. It is specifically designed for solving the most difficult problems requiring extended thought processes, delivering deeper insights for advanced R&D applications.
What’s the difference between Gemini 3 Pro and Gemini 3 Deep Think?⌄
Gemini 3 Pro is the standard model of the gemini 3 api for fast responses, while Gemini 3 Deep Think is a reasoning mode of the gemini 3 pro api that uses deeper thinking for more accurate results on complex tasks.
| Input | 125 credits 1M tokens≈ $0.63 |
| Output | 875 credits 1M tokens≈ $4.38 |
Billed per token: input and output are priced separately, and thinking tokens count as output. The Playground charges exactly the same way.
Read API docs →curl https://ai.modelfold.online/v1/chat/completions \
-H "Authorization: Bearer $MODELFOLD_API_KEY" \
-H "Content-Type: application/json" \
-d '{"model":"gemini-3-pro","messages":[{"role":"user","content":"Hello"}]}'