 ModelFold
elevenlabs/text-to-dialogue-v3
ElevenLabs Eleven V3 enables expressive multilingual Text to Dialogue with audio tag control, multi-speaker support, and natural delivery, designed for dialogue-driven applications, storytelling tools, and immersive voice experiences.
Pricing: Billed by length: 18 credits per 1,000 characters (partial thousands round up), minimum 8 credits.
Explore more Text to Speech models
Latest and popular AI models
Affordable Eleven V3 API for Multilingual Text to Dialogue
Build natural, emotionally expressive dialogue experiences across 70+ languages with fine-grained control, multi-speaker generation, and flexible deployment through the ModelFold platform.
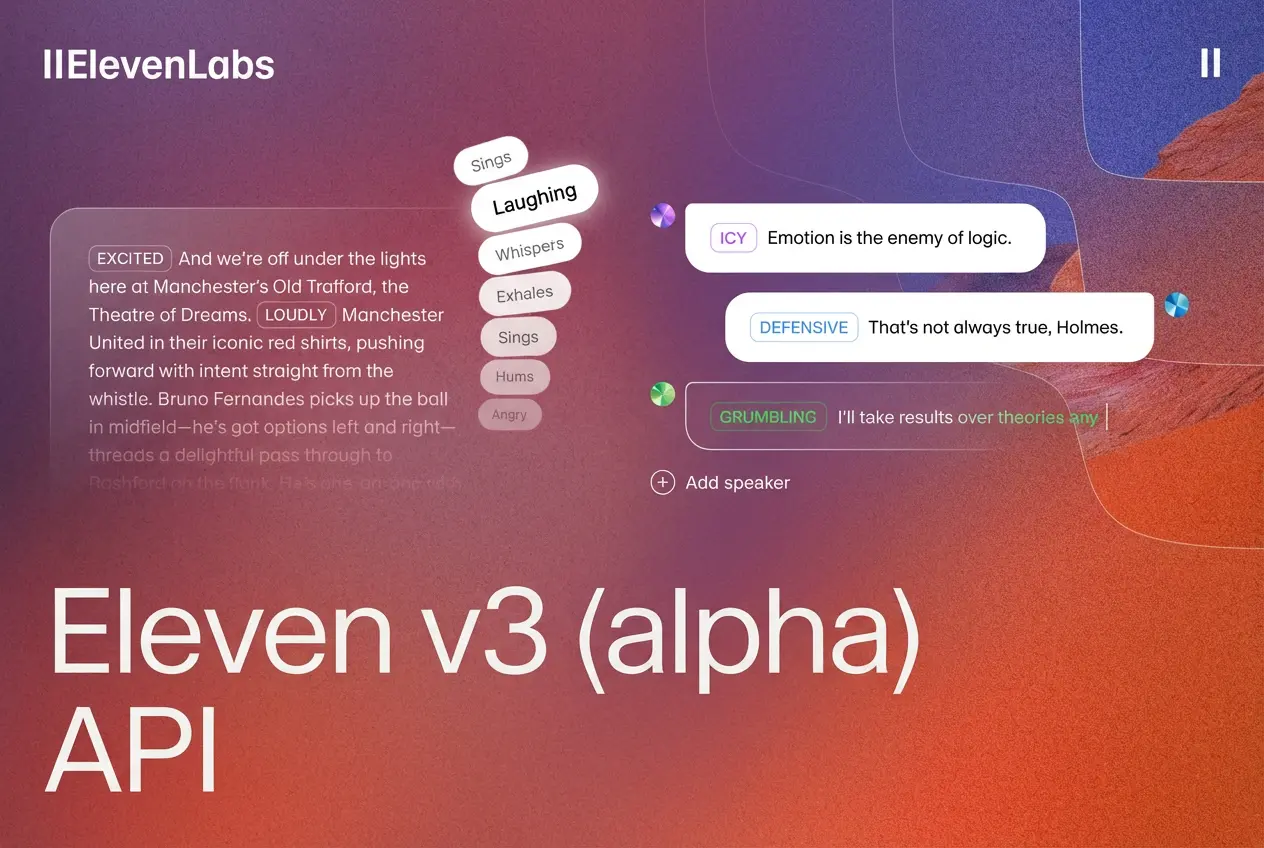
From Expressive Speech to Natural Audio Dialogues with ElevenLabs V3 API
Eleven V3 (Alpha) is ElevenLabs’ most expressive Text to Speech model to date, designed to sound less like synthesis and more like real performance. It goes beyond traditional AI voice generation by understanding emotional nuance, pacing, and context—allowing voices to whisper, laugh, sigh, interrupt, and react in ways that feel natural and alive. This deeper level of expressiveness is powered by innovations such as inline audio tags, multi-speaker dialogue mode, and expanded language understanding across 70+ languages, unlocking new possibilities for dynamic voice experiences and immersive audio storytelling. The ElevenLabs V3 API brings these capabilities directly into production workflows through advanced Text to Speech and multi-speaker Text to Dialogue. With Eleven V3 API, teams can design expressive narration, realistic conversations, and emotionally rich audio experiences that feel directed rather than generated. As Eleven V3 (Alpha) API continues to evolve, it opens the door to a new class of creative, voice-first products across media, entertainment, education, and interactive applications.
What’s New In Eleven V3 (Alpha) API
Audio Tags for Expressive Control in Eleven V3 (Alpha) API
Eleven V3 (Alpha) API introduces inline audio tags that allow fine-grained control over tone, emotion, and non-verbal reactions directly within the text. Through the ElevenLabs V3 API, creators can guide delivery with cues such as whispering, laughter, hesitation, or emphasis, making speech feel intentional and expressive rather than mechanically generated.
Natural Text to Dialogue and Multi-Speaker Conversations in ElevenLabs V3 API
With Text to Dialogue, the ElevenLabs V3 API enables multi-speaker conversations that feel natural in timing, pacing, and interaction. Eleven V3 API supports realistic turn-taking and interruptions, allowing teams to create flowing conversations for podcasts, games, storytelling, and dialogue-heavy audio experiences without manually stitching together separate voice tracks.
Global Voice Coverage with 70+ Languages in Eleven V3 API
The Eleven V3 API supports expressive speech generation across more than 70 languages, covering high-demand global markets. Through the ElevenLabs V3 API, both Text to Speech and Text to Dialogue workflows can maintain nuance, prosody, and emotional delivery across languages, making it suitable for multilingual products and international audiences.
More Natural Text to Speech with Deeper Text Understanding in ElevenLabs V3 API
ElevenLabs V3 API demonstrates deeper understanding of text input, resulting in improved stress, cadence, and overall expressiveness for Text to Speech generation. Eleven V3 (Alpha) API is better able to interpret context and intent from scripts, allowing generated speech to carry more natural rhythm and emotional continuity across longer passages.
How to Deploy Eleven V3 API on ModelFold for Text to Dialogue
Get started with our product in just a few simple steps...
- 1
1. Register on ModelFold and Get Your Eleven V3 API Key
Create an account on ModelFold and generate your API Key to unlock access to Eleven V3 API. Your key authenticates requests to the ElevenLabs V3 API and allows you to begin building with expressive voice capabilities.
- 2
2. Test ElevenLabs V3 API Free in the Playground
Use the ModelFold playground to explore the ElevenLabs V3 API before deployment. You can freely test expressive generation, experiment with audio tags, and preview multi-speaker Text to Dialogue behavior without integrating into your production environment.
- 3
3. Configure Eleven V3 API Requests for Your Product
After testing, define how you will structure requests for Eleven V3 API in your application. On ModelFold, write the dialogue in prompt with one line per turn ("Speaker 1: …" / "Speaker 2: …") and pick a voice for each speaker with voice / voice_2; for more than two voices, send the upstream dialogue array (text + voice per line) directly. All lines together can be up to 5,000 characters.
- 4
4. Integrate ElevenLabs V3 API into Your Backend or Workflow
Deploy the ElevenLabs V3 API into your application, service, or internal workflow with a POST request to https://ai.modelfold.online/v1/audio/generations; the response returns the finished audio URL. Teams commonly integrate Eleven V3 API to power voice features in creative platforms, media tools, education products, and interactive experiences.
- ✓
5. Scale Your Usage with Eleven V3 API on ModelFold
Once deployed, you can scale Eleven V3 API usage on ModelFold as your product grows. The same integration supports simple voice generation as well as more advanced dialogue experiences, allowing your use cases to evolve without changing your technical foundation.
Guidelines for More Expressive Text to Speech with ElevenLabs V3 API
Split large inputs into smaller segments for more reliable generation
When working with long scripts or complex Text to Dialogue prompts in Eleven V3 API, avoid submitting very large blocks of text in a single request. Instead, divide content into logical segments such as scenes, paragraphs, or speaker turns. This improves stability, preserves expressive quality, and makes it easier to refine individual sections without regenerating the entire output.
Use audio tags sparingly for clearer and more natural delivery
Audio tags are most effective when used with intention rather than density. In Eleven V3 API, placing tags at key emotional beats—such as moments of hesitation, reaction, or tonal shift—tends to produce more natural results. Common tags like [whispers], [laughs], [sarcastic], [excited], or [sighs] can subtly guide delivery when applied thoughtfully. Overusing audio tags can reduce consistency and make dialogue feel overly stylized, so it is best to treat them as light direction rather than continuous markup.
Use ellipses (…) to shape pauses and hesitation naturally
Ellipses are a simple but effective way to influence pacing in Eleven V3 API. They often introduce subtle pauses, trailing thoughts, or hesitation in delivery. Writing text such as “I’m not sure… maybe we should wait” typically produces a more natural rhythm than a continuous sentence. This technique is especially useful in Text to Dialogue where conversational timing plays an important role.
Use dashes (—) to simulate interruptions and broken speech
Dashes can be used to indicate that a speaker is interrupted or abruptly changes direction mid-sentence. For example, text like “I was about to tell you—wait, did you hear that?” often results in more realistic conversational flow. In Eleven V3 API, punctuation such as this works alongside audio tags to shape timing, rhythm, and dialogue dynamics.
Generate multiple variations and select the best performance
Expressive voice generation is not fully deterministic. When using ElevenLabs V3 API in creative workflows, it is common to generate multiple versions of the same input and choose the most natural result. Small changes in punctuation, audio tag placement, or phrasing can meaningfully affect delivery, making iteration a practical part of production.
How Teams Are Using ElevenLabs V3 API to Build Voice Experiences
Storytelling and Audiobooks with ElevenLabs V3 API
ElevenLabs V3 API is well suited for long-form narration where delivery matters as much as clarity. With expressive Text to Speech, creators can produce audiobooks, short stories, and narrative content that carry emotion, pacing, and character, allowing spoken content to feel closer to performance than flat narration.
Podcasts and Scripted Conversations with Eleven V3 API
For dialogue-heavy formats, Eleven V3 API enables natural multi-speaker Text to Dialogue that supports realistic timing, interruptions, and emotional continuity. This makes it practical to generate podcast-style episodes, interview simulations, or scripted conversations without manually assembling separate voice tracks.
Character Dialogue for Games with Eleven V3 (Alpha) API
Eleven V3 (Alpha) API is particularly valuable in game development and interactive storytelling, where characters require believable voice and personality. Teams can use it to create NPC dialogue, branching conversations, and narrative-driven interactions that enhance immersion and make experiences feel more responsive and alive.
Voiceovers and Creative Media Production with ElevenLabs V3 API
Many creators and product teams use ElevenLabs V3 API for video narration, AI avatars, and creative media workflows where tone and delivery define the experience. With expressive Text to Speech, voiceovers can align more closely with visual storytelling, making generated audio feel intentional rather than generic.
Why Developers Choose ModelFold to Deploy Eleven V3 API
Affordable Eleven V3 API Pricing for Real-World Usage
ModelFold offers affordable access to ElevenLabs V3 API, making Eleven V3 API practical not only for experimentation but also for real production use. Teams can better control costs while still benefiting from expressive voice capabilities powered by Eleven V3 (Alpha) API.
Complete ElevenLabs V3 API Documentation for Faster Integration
ModelFold provides complete ElevenLabs V3 API Documentation covering onboarding, core features, request structure, and deployment workflows. This helps developers understand how to use Eleven V3 API efficiently, reduce integration friction, and move from testing to production with confidence.
24/7 Support for Eleven V3 (Alpha) API Deployments
When building production features with Eleven V3 (Alpha) API, reliability matters. ModelFold provides 24/7 support to assist with technical questions, integration issues, and ongoing usage of ElevenLabs V3 API, helping teams keep their products running smoothly.
Flexible Credit-Based Access Instead of Fixed Subscriptions
ModelFold uses a flexible credit-based system for accessing Eleven V3 API rather than forcing rigid subscription plans. This allows teams to scale usage based on real demand, control spending more precisely, and adopt ElevenLabs V3 API at their own pace.
FAQs About ElevenLabs Eleven V3 (Alpha) API
What is the main focus of ElevenLabs V3 API?⌄
ElevenLabs V3 API focuses on expressiveness rather than only clarity. It improves emotional nuance, pacing, and delivery, allowing generated speech to sound more natural and dynamic. It is designed for scenarios where performance and delivery quality matter.
What does the “alpha” label mean for Eleven V3 (Alpha) API?⌄
Eleven V3 (Alpha) API indicates that the system is still evolving. Outputs may be more variable than earlier versions, and users often need to experiment with prompts, structure, and tags to achieve consistent results.
Where can I find ElevenLabs V3 API Documentation?⌄
ElevenLabs V3 API Documentation typically includes guidance on prompt structure, dialogue formatting, supported features, and best practices for generation. Reviewing documentation and structured examples helps improve understanding and output quality.
How do I get an ElevenLabs V3 API Key on ModelFold?⌄
An ElevenLabs V3 API Key is generated after registering on ModelFold and accessing the developer dashboard. This key is used to authenticate requests when integrating the API into applications or tools.
Is there an ElevenLabs V3 API free test available?⌄
ElevenLabs V3 API free test access is usually provided through playground-style environments, allowing users to experiment with prompts, voices, tags, and dialogue formats before integrating the API into their own workflows.
Does ElevenLabs V3 API support multi-speaker dialogue?⌄
Yes. ElevenLabs V3 API supports native multi-speaker dialogue generation, allowing multiple voices to interact within a single output. This makes it possible to generate conversations with natural turn-taking, interruptions, and emotional continuity.
How can I improve output quality when using Eleven V3 API?⌄
With Eleven V3 API, output quality improves when text is clearly structured and when punctuation is used intentionally. Splitting long scripts into smaller segments, using ellipses for pauses, and applying audio tags thoughtfully can significantly improve naturalness.
What level of control do audio tags provide in Eleven V3 (Alpha) API?⌄
Eleven V3 (Alpha) API supports a wide range of audio tags that influence tone, emotion, delivery style, and non-verbal expression. Tags such as [whispers], [laughs], or [hesitant] can guide how the voice performs without changing the underlying text.
| Text To Dialogue V3 | 18 credits / 1,000 chars · min 8 |
The estimate is held when the task starts; once it finishes, the charge is settled to the actual upstream usage (refund or top-up), never below the minimum.
curl https://ai.modelfold.online/v1/audio/generations \
  -H "Authorization: Bearer $MODELFOLD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"elevenlabs/text-to-dialogue-v3","prompt":"Speaker 1: Hello!\nSpeaker 2: Hi there.","voice":"EkK5I93UQWFDigLMpZcX"}'