 ModelFold
deepseek-v4-1-flash
DeepSeek-V4.1-Flash is a multimodal model designed for faster inference, higher throughput, and stronger performance across reasoning, coding, visual understanding, and agentic tasks. Its architecture improves efficiency while preserving the capabilities needed for complex, multi-step workloads.
Pricing: Input 30 credits / 1M tokens (≈ $0.15), Output 118.75 credits / 1M tokens (≈ $0.59).
How can I help you today?
Explore more Chat models

Latest and popular AI models
DeepSeek-V4.1-Flash API for Fast and Efficient Multimodal Reasoning
Use DeepSeek-V4.1-Flash API for responsive reasoning, native visual understanding, coding, and agentic workflows with an architecture built for efficient inference and high throughput.
Key Features of DeepSeek-V4.1-Flash API
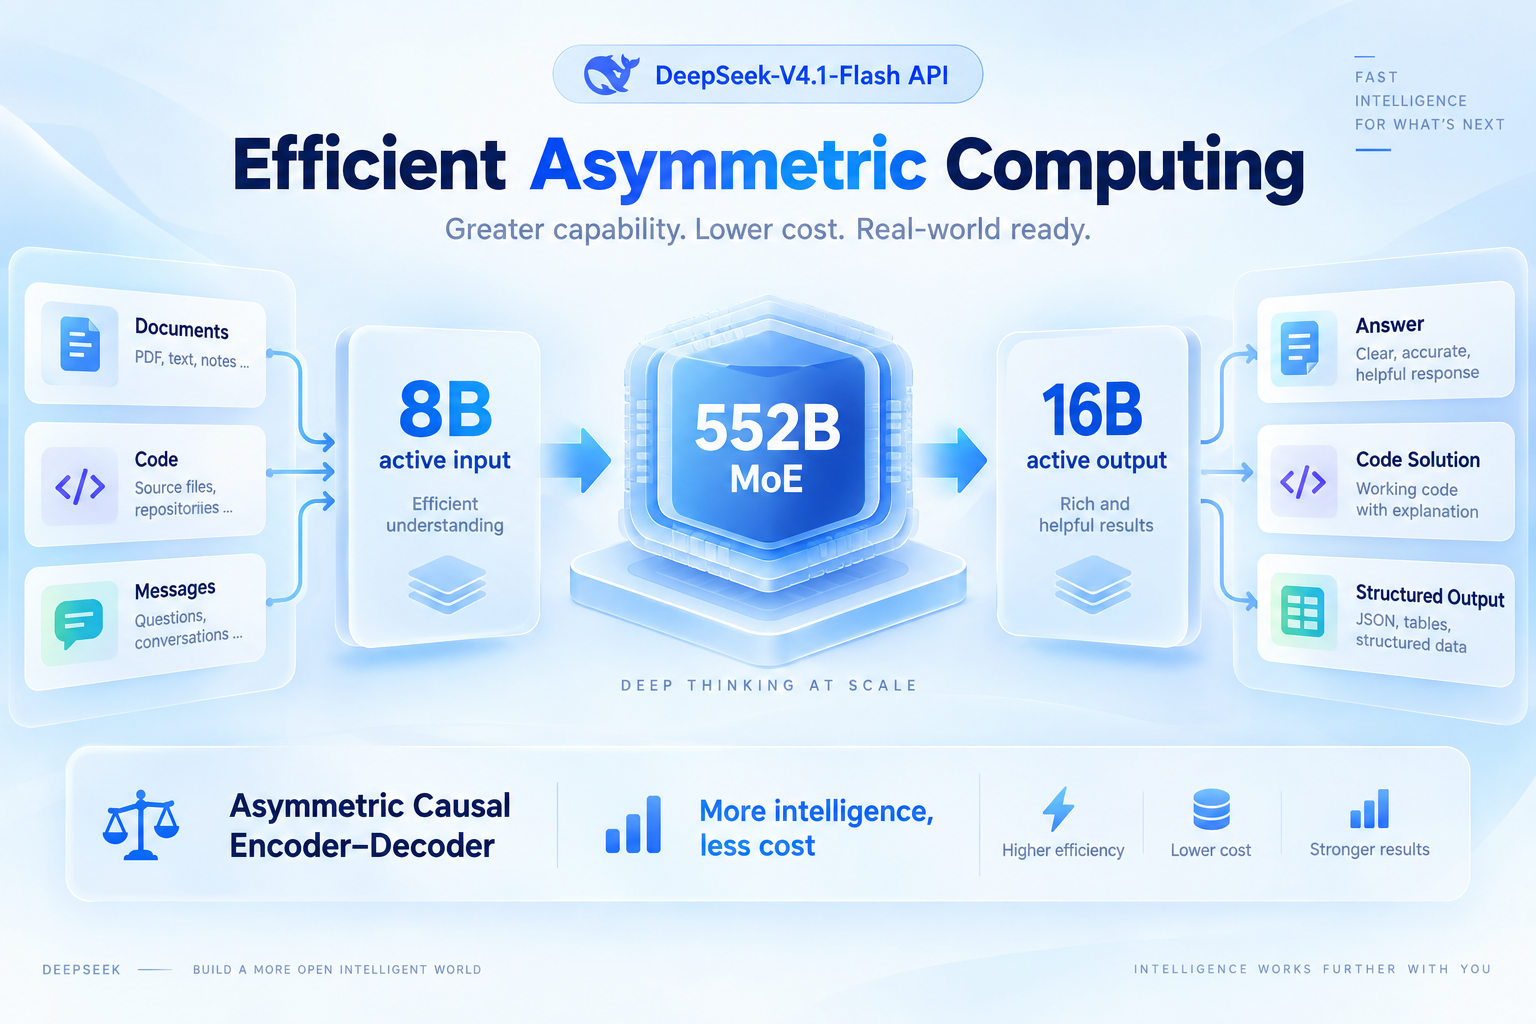
DeepSeek-V4.1-Flash API Brings Efficient Asymmetric Computing
Built on a 552B-parameter Mixture-of-Experts backbone, DeepSeek-V4.1-Flash API uses a new Causal Encoder–Decoder architecture with asymmetric computation across input and output. The model activates about 8B parameters per token during input processing and 16B during output generation, reducing active computation relative to its total model capacity.
Native Visual Understanding Comes with DeepSeek V4.1 Flash API
Rather than treating vision as a separate add-on, DeepSeek V4.1 Flash API natively processes images and text within the same multimodal architecture. Visual embeddings and text embeddings are jointly processed from language-model pretraining, giving the model built-in support for image-based understanding alongside textual reasoning.

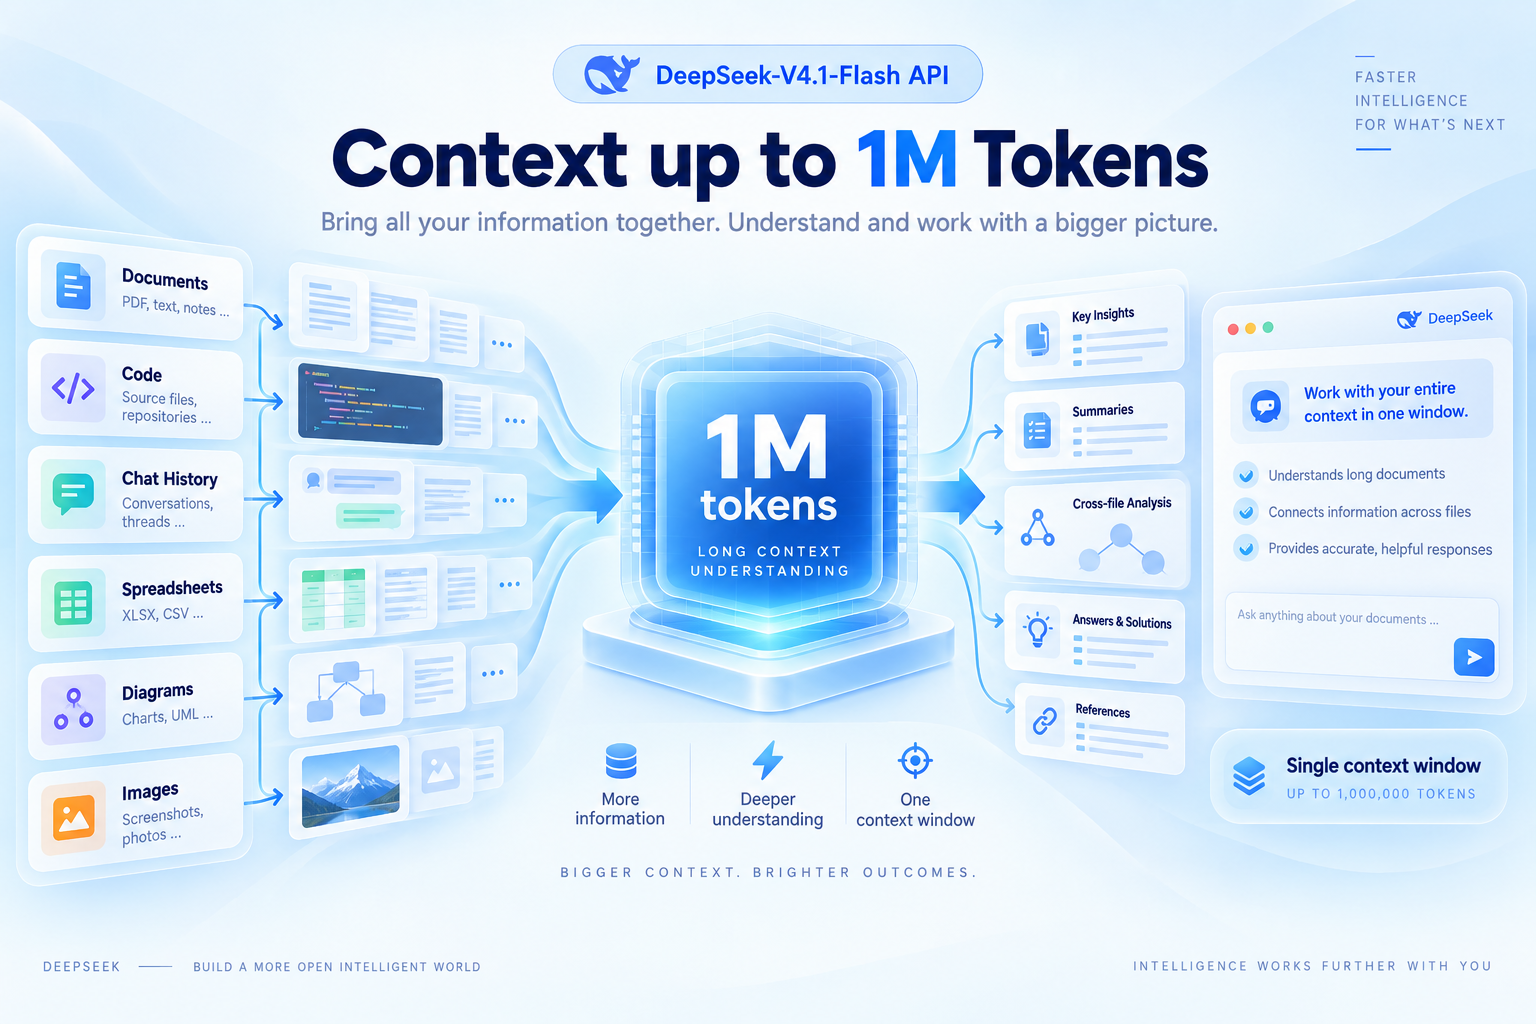
DeepSeek 4.1 Flash API Extends Context to One Million Tokens
For information-heavy workloads, DeepSeek 4.1 Flash API supports context lengths of up to one million tokens. This expanded context capacity allows the model to process substantially larger bodies of text, code, conversation history, and multimodal information within a single context window.
A Compressed KV Cache Makes DeepSeek API Workloads More Efficient
DeepSeek API applications using V4.1-Flash benefit from a substantially smaller persistent KV cache than the previous V4-Flash generation. DeepSeek reports that the new design requires about one-quarter of the HBM and one-eighth of the SSD storage, reducing cache overhead for workloads that process or reuse large contexts.
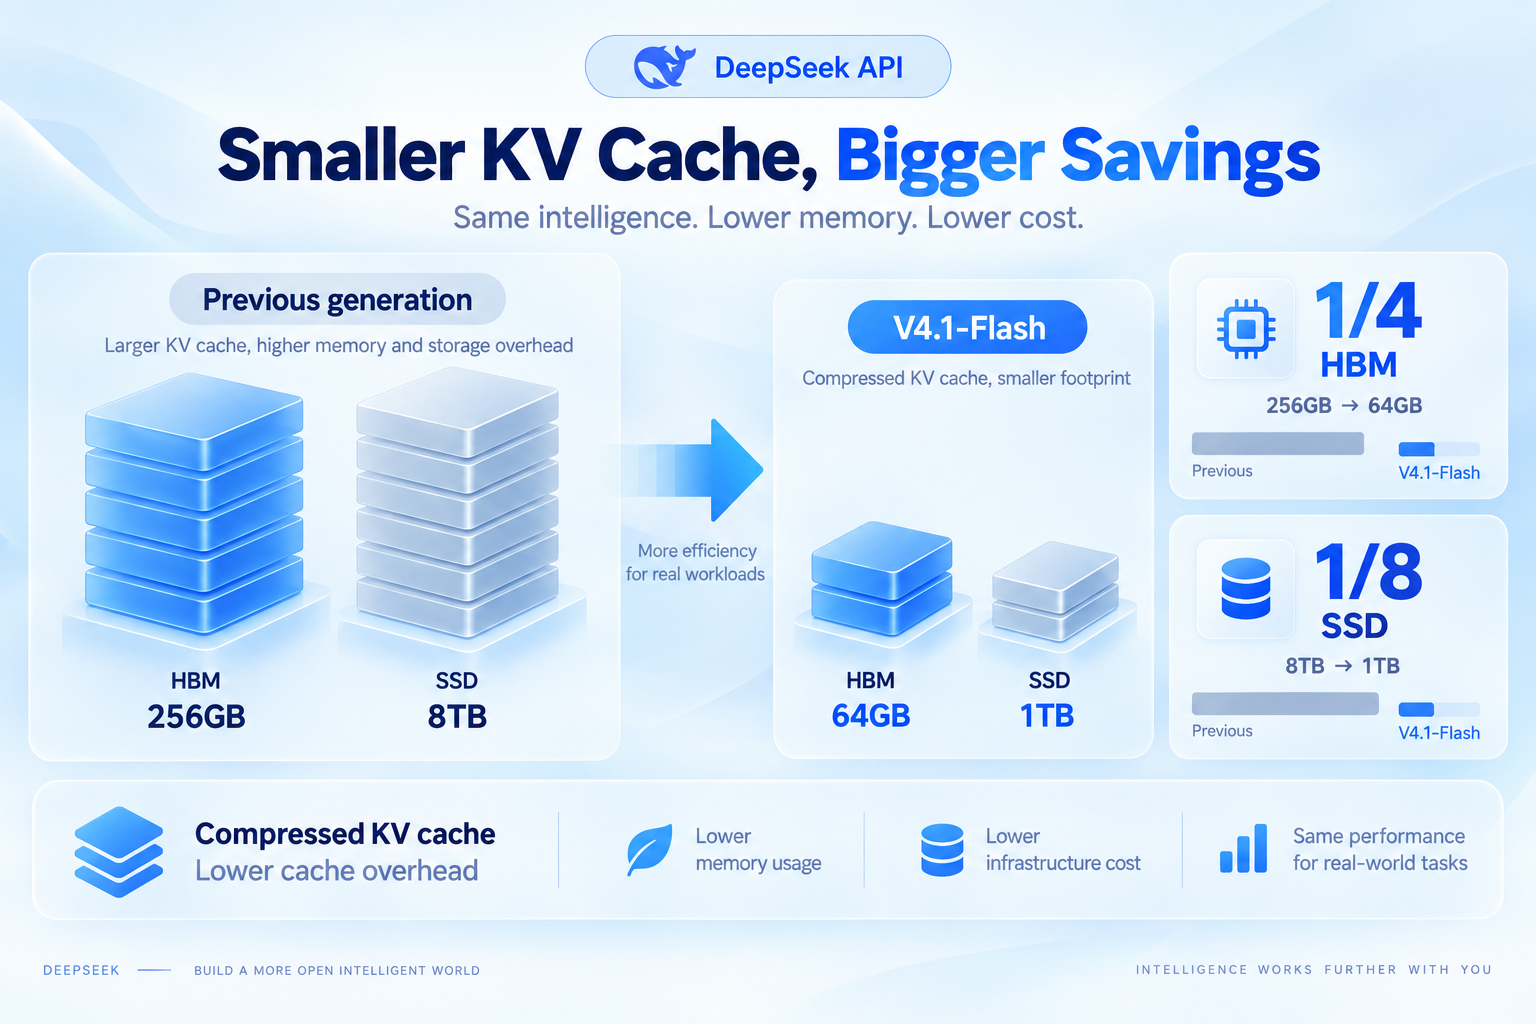
Built for Higher Throughput, DeepSeek-V4.1-Flash API Fits Agentic Workloads
DeepSeek-V4.1-Flash API is designed for faster inference and higher throughput, while its Causal Encoder–Decoder architecture improves efficiency for input-heavy agentic workloads. These characteristics make it particularly relevant to applications that involve long prompts, repeated context processing, tool interaction, coding, and multi-step model execution.

How DeepSeek-V4.1-Flash Performs Across Demanding Tasks
DeepSeek-V4.1-Flash benchmark results reflect improvements across a wide mix of demanding workloads rather than a single capability area. Compared with the earlier V4-Flash generation, the model posts stronger results in coding, repository-level software engineering, terminal tasks, automation, and tool-assisted reasoning, while remaining competitive on broader reasoning and multimodal evaluations. The table below shows how DeepSeek-V4.1-Flash performs across the full benchmark set alongside other leading models.
| Benchmarks | DeepSeek V4.1-Flash | DeepSeek V4-Pro 0813 | DeepSeek V4-Flash 0731 | GLM 5.3 | Kimi K3 | GPT 5.6-Sol | Claude Opus 5 |
|---|---|---|---|---|---|---|---|
| GPQA Diamond | 90.9 | 92.4 | 89.9 | 88.1 | 92.9 | 94.1 | 93.4 |
| HLE | 36.8 (39.1*) | 42.7* | 37.8* | 42.0* | 43.5 | 44.5 | 56.3 |
| Codeforces (Rating) | 3471 | 3348 | 3289 | — | — | — | — |
| MathArena Apex | 65.6 | 65.3 | 58.6 | — | 65.6 | — | — |
| Terminal-Bench 2.1 | 90.6 | 87.9 | 82.7 | 88.2 | 88.3 | 88.8 | 89.1 |
| Terminal-Bench 3.0 | 30.0 | 11.8 | 7.6 | 28.3 | 17.7 | 34.4 | 43.3 |
| Terminal-Bench 4.0 | 31.2 | 12.4 | 7.0 | 37.9 | 12.6 | 39.9 | 51.8 |
| DeepSWE v1.1 | 74.2 | 62.7 | 54.4 | 66.9 | 67.5 | 73.0 | 74.0 |
| ProgramBench | 20.3 | 15.5 | — | 19.0 | 17.5 | 23.0 | 37.0 |
| NL2Repo-Bench | 65.4 | 61.5 | 54.2 | 58.0 | 58.0 | 56.8 | 75.3 |
| CyberGym | 88.1 | 83.3 | 76.7 | 84.5 | 80.0 | 84.5 | — |
| SEC-Bench Pro | 62.8 | 56.4 | 30.9 | — | — | 74.3 | — |
| ExploitGym | 15.3 | 5.4 | 1.8 | 15.0 | — | 33.7 | 22.1 |
| HLE (w/tools) | 63.9 | 60.0 | 51.5 | 62.5 | 59.8 | — | 63.6 |
| Automation-Bench | 54.8 | 43.2 | 37.7 | 48.8 | 46.7 | 45.8 | 50.3 |
| Agents' Last Exam | 31.8 | 25.7 | 25.2 | 28.5 | 27.6 | 26.7 | 28.6 |
| Chartography (w/tools) | 78.9 | — | — | — | 68.1 | 79.9 | 84.0 |
| BabyVision (w/tools) | 89.6 | — | — | — | 85.7 | 88.9 | 94.1 |
| ZeroBench-main (w/tools) | 49.0 | — | — | — | 41.0 | 53.0 | 52.0 |
| Note | * Denotes the text-only subset of HLE. | — | — | — | — | — | — |
How to Get Started with DeepSeek-V4.1-Flash API
You can move from account setup to testing and deployment in three straightforward steps. Start by getting your API key, validate the model in the Playground, then connect DeepSeek-V4.1-Flash API to your own application or workflow.
- 1
1. Sign Up on ModelFold and Get Your DeepSeek-V4.1-Flash API Key
Create a ModelFold account or sign in to your existing account, then obtain the API key needed to access DeepSeek-V4.1-Flash API. Keep the key secure and use it to authenticate requests when you begin testing or integrating the model.
- 2
2. Test DeepSeek V4.1 Flash API in the Playground
Before deployment, use the Playground to try DeepSeek V4.1 Flash API with sample prompts and inputs. You can quickly check response quality, experiment with different instructions.
- ✓
3. Deploy DeepSeek 4.1 Flash API in Your Application
Once testing is complete, integrate DeepSeek 4.1 Flash API into your product, agent, backend service, or automation workflow. Configure your requests around your application requirements and move from Playground experiments to production-ready API calls.
What Can You Build with DeepSeek-V4.1-Flash API
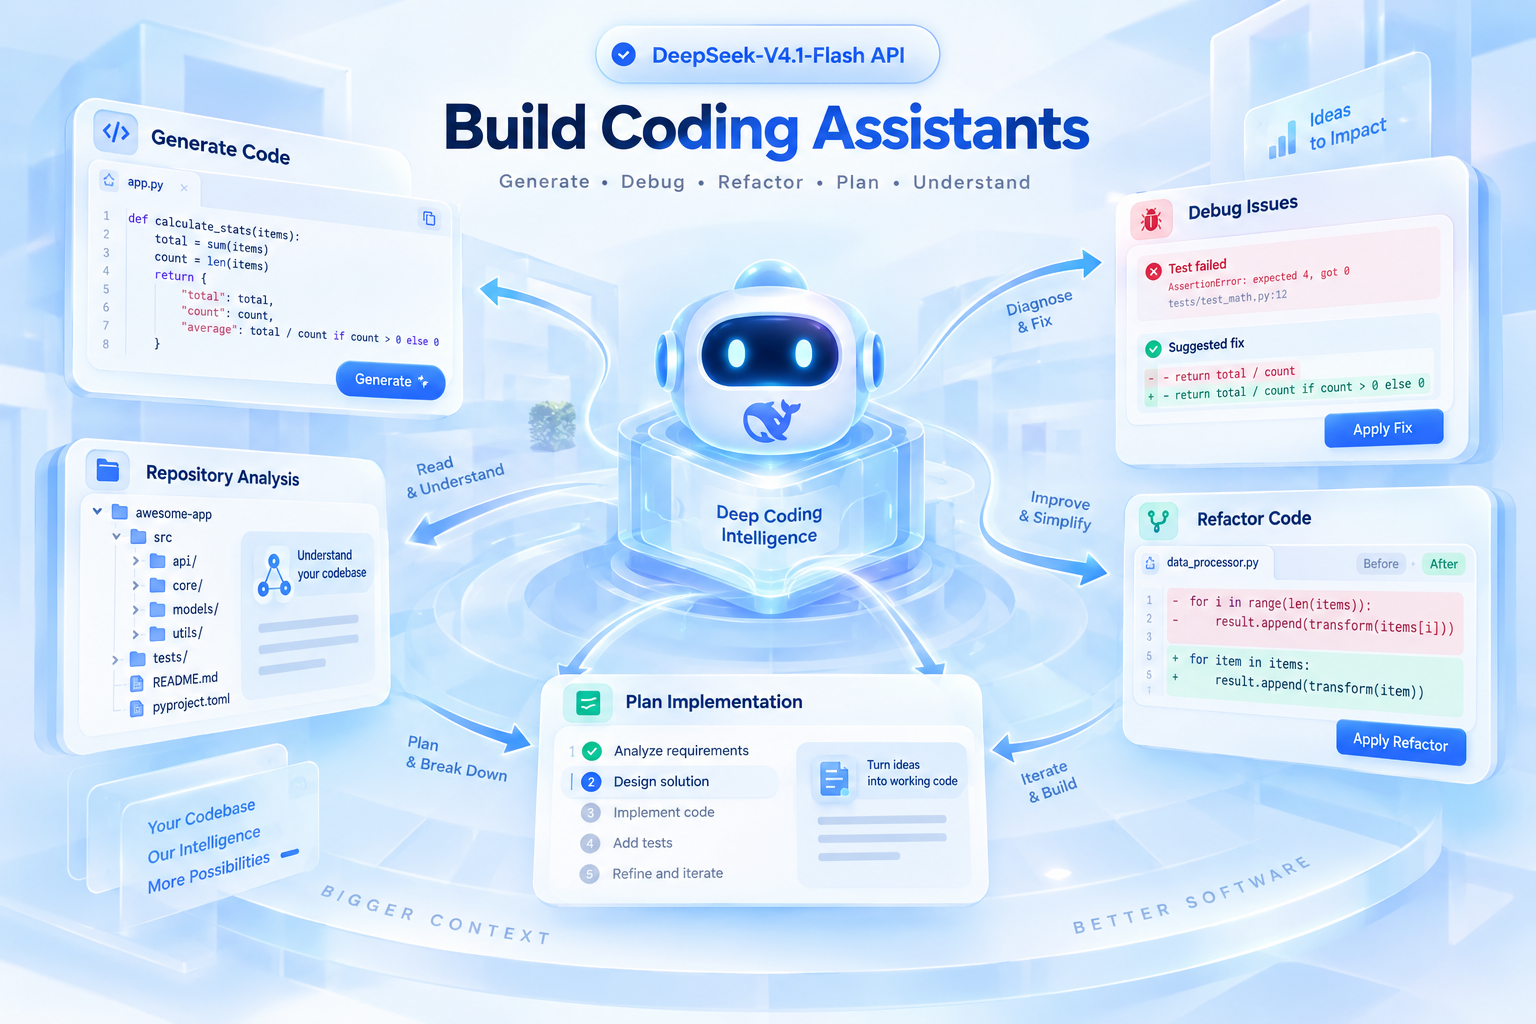
Build Coding Assistants with DeepSeek-V4.1-Flash API
DeepSeek-V4.1-Flash API can support code generation, debugging, refactoring, implementation planning, and repository-level analysis. Developers can use it to build coding assistants that work across larger code contexts and handle more involved software engineering tasks from planning through iterative development.
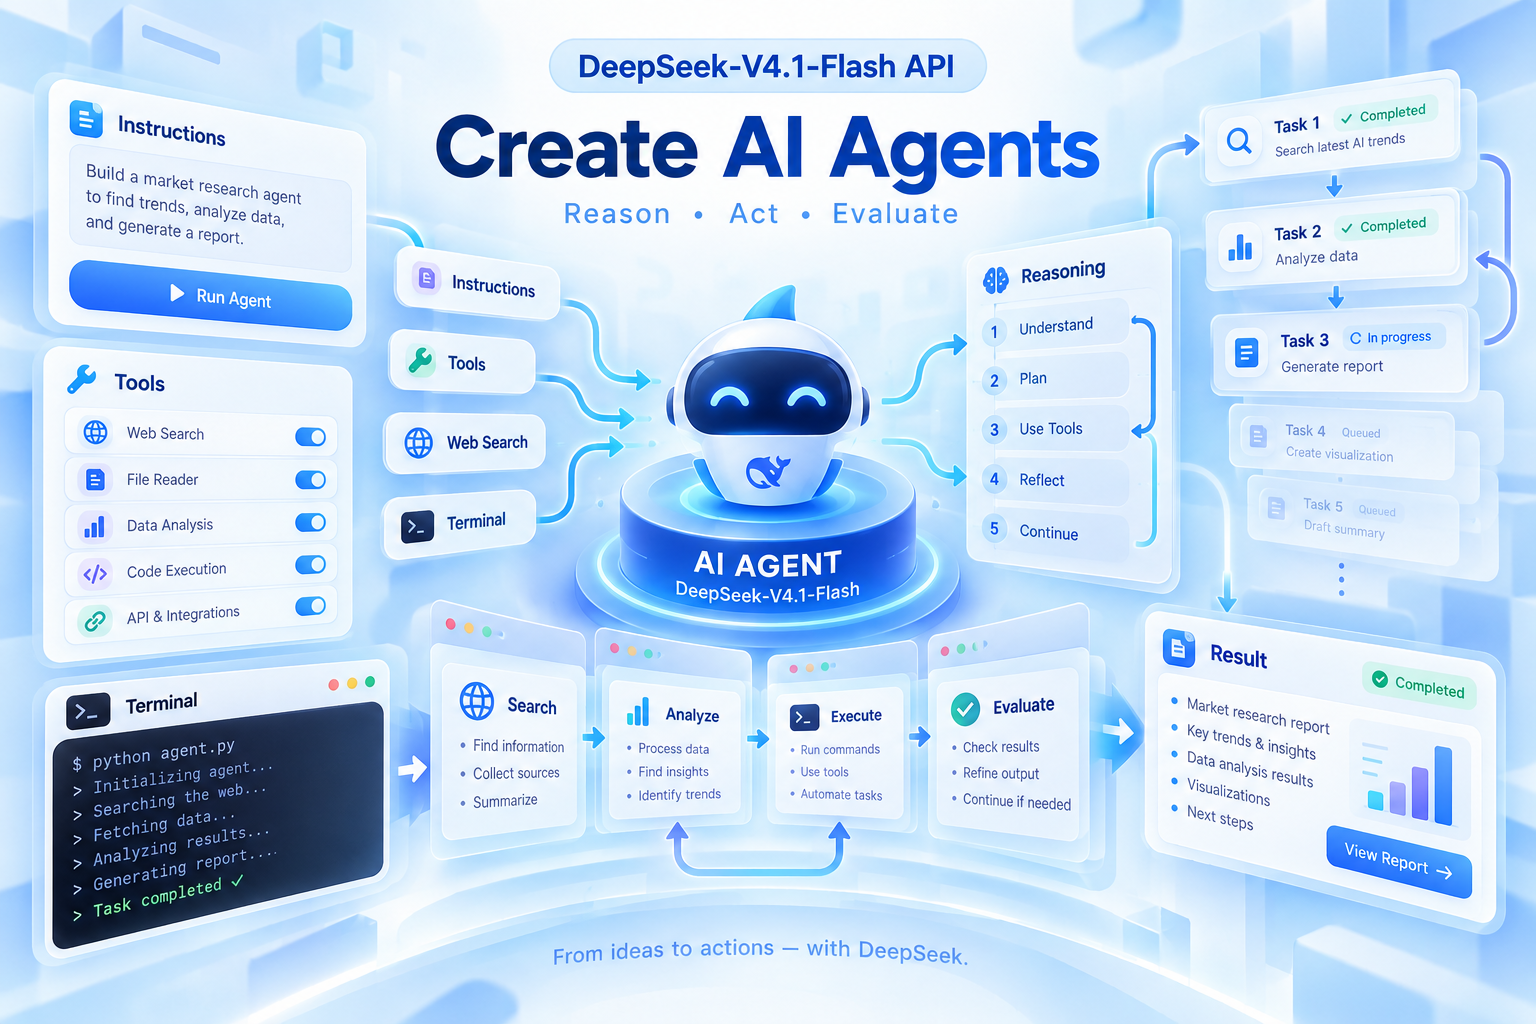
Create AI Agents with DeepSeek V4.1 Flash API
DeepSeek V4.1 Flash API fits agentic workflows that involve repeated reasoning, tool interaction, terminal operations, and multi-step execution. It can support assistants that interpret instructions, take actions, evaluate intermediate results, and continue working across longer task sequences.
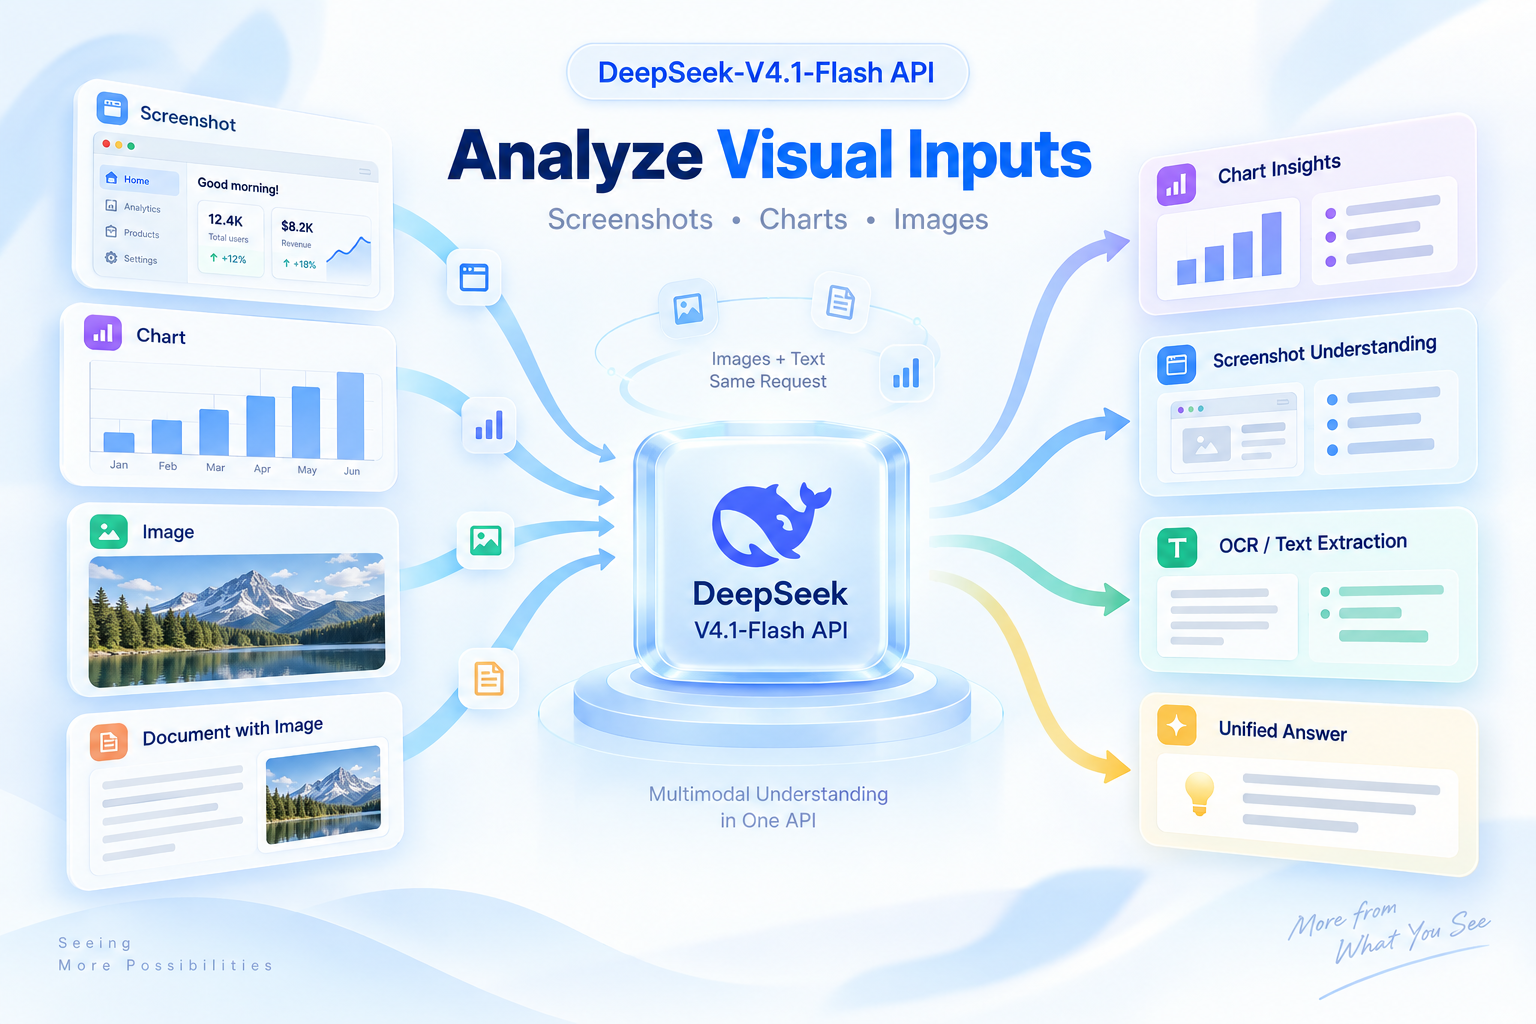
Analyze Visual Inputs with DeepSeek 4.1 Flash API
DeepSeek 4.1 Flash API supports native multimodal understanding for images alongside text. Developers can use it to build workflows that interpret screenshots, read text from images, analyze charts, and reason about other visual content within the same request.
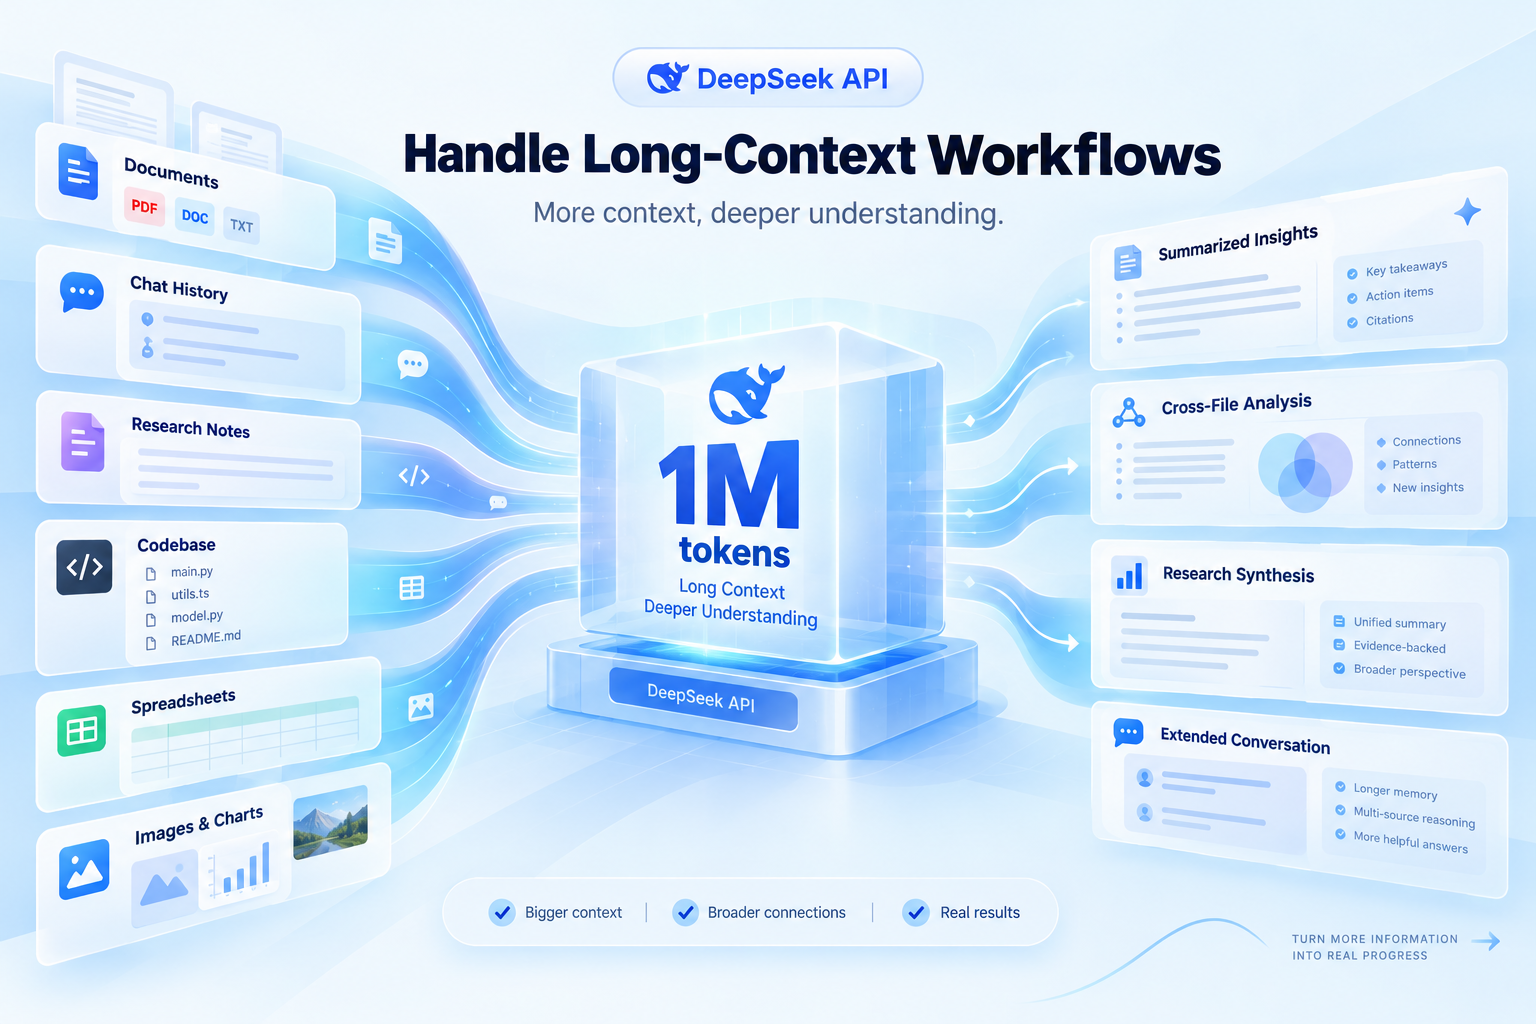
Handle Long-Context Workflows with DeepSeek API
DeepSeek API can support long-context tasks such as extended conversations, research workflows, large codebase understanding, and other information-heavy tasks with V4.1-Flash. Its expanded context capacity helps keep more relevant information available across complex workflows without constantly breaking inputs into smaller pieces.
Why Choose ModelFold for DeepSeek-V4.1-Flash API Integration
One OpenAI-Compatible Endpoint
Send model deepseek-v4-1-flash to POST https://ai.modelfold.online/v1/chat/completions with Authorization: Bearer YOUR_API_KEY and an OpenAI-style messages array. The full response comes back in one JSON body with token usage and the credits charged. Pricing is shown in the pricing section above.
Thinking On by Default, Adjustable in the Playground
DeepSeek-V4.1-Flash thinks before it answers by default. In the Playground on this page you can turn thinking off for faster, cheaper replies, or choose a reasoning effort level, and compare the results before you integrate.
Same Integration as Every Other Model
Because every chat model on ModelFold uses the same endpoint and request format, you can switch between DeepSeek, Claude, GPT, Gemini, Grok and Kimi by changing only the model id, with one API key and one wallet.
Pay Only for What You Use
Billing is per token with no subscription, and every call shows its exact cost in the response and in your wallet history, so testing DeepSeek V4.1 Flash on real prompts costs only a few credits.
FAQs About DeepSeek-V4.1-Flash API
What is DeepSeek-V4.1-Flash?⌄
DeepSeek-V4.1-Flash is a multimodal Mixture-of-Experts model built on a 552B-parameter backbone and a Causal Encoder–Decoder architecture. It uses asymmetric computation across input and output, with about 8B active parameters for input processing and 16B for output generation, while also supporting native visual understanding and long-context tasks.
What can I build with DeepSeek-V4.1-Flash API?⌄
DeepSeek-V4.1-Flash API can be used for coding assistants, AI agents, terminal workflows, visual understanding, research tools, long-context reasoning, and other applications that require multi-step execution. Its design is especially relevant to workloads that involve large inputs or repeated model calls.
Does DeepSeek V4.1 Flash API support image input?⌄
Yes. DeepSeek V4.1 Flash API includes native multimodal capabilities, allowing applications to combine images with text prompts. It can be used to interpret screenshots, extract or understand text visible in images, analyze charts, and reason about other visual content.
How large is the context window of DeepSeek 4.1 Flash API?⌄
DeepSeek 4.1 Flash API supports a context window of up to one million tokens. This gives developers more room for large codebases, extensive conversation history, research material, and other information-heavy inputs within a single context.
Why does DeepSeek-V4.1-Flash API use an asymmetric architecture?⌄
The asymmetric Causal Encoder–Decoder design allows DeepSeek-V4.1-Flash API to use different amounts of active computation for input and output. Around 8B parameters are activated during input processing and 16B during generation, helping reduce computation while retaining the capacity of the larger MoE backbone.
Is DeepSeek API suitable for agentic applications?⌄
Yes. DeepSeek API with V4.1-Flash is designed for workloads involving repeated reasoning, tool interaction, terminal tasks, and multi-step execution. Its higher-throughput architecture and reduced cache requirements are particularly relevant to agents that process large amounts of context over longer task sequences.
How can I access DeepSeek-V4.1-Flash API on ModelFold?⌄
Create a ModelFold account, obtain your API key, and use the available Playground or API documentation to test DeepSeek-V4.1-Flash API before integration. Once your request setup is ready, you can connect the API to your application, backend service, coding assistant, or agent workflow.
| Input | 30 credits 1M tokens≈ $0.15 |
| Output | 118.75 credits 1M tokens≈ $0.59 |
Billed per token: input and output are priced separately, and thinking tokens count as output. The Playground charges exactly the same way.
Read API docs →curl https://ai.modelfold.online/v1/chat/completions \
-H "Authorization: Bearer $MODELFOLD_API_KEY" \
-H "Content-Type: application/json" \
-d '{"model":"deepseek-v4-1-flash","messages":[{"role":"user","content":"Hello"}]}'