 ModelFold
volcengine/video-to-video-lip-sync
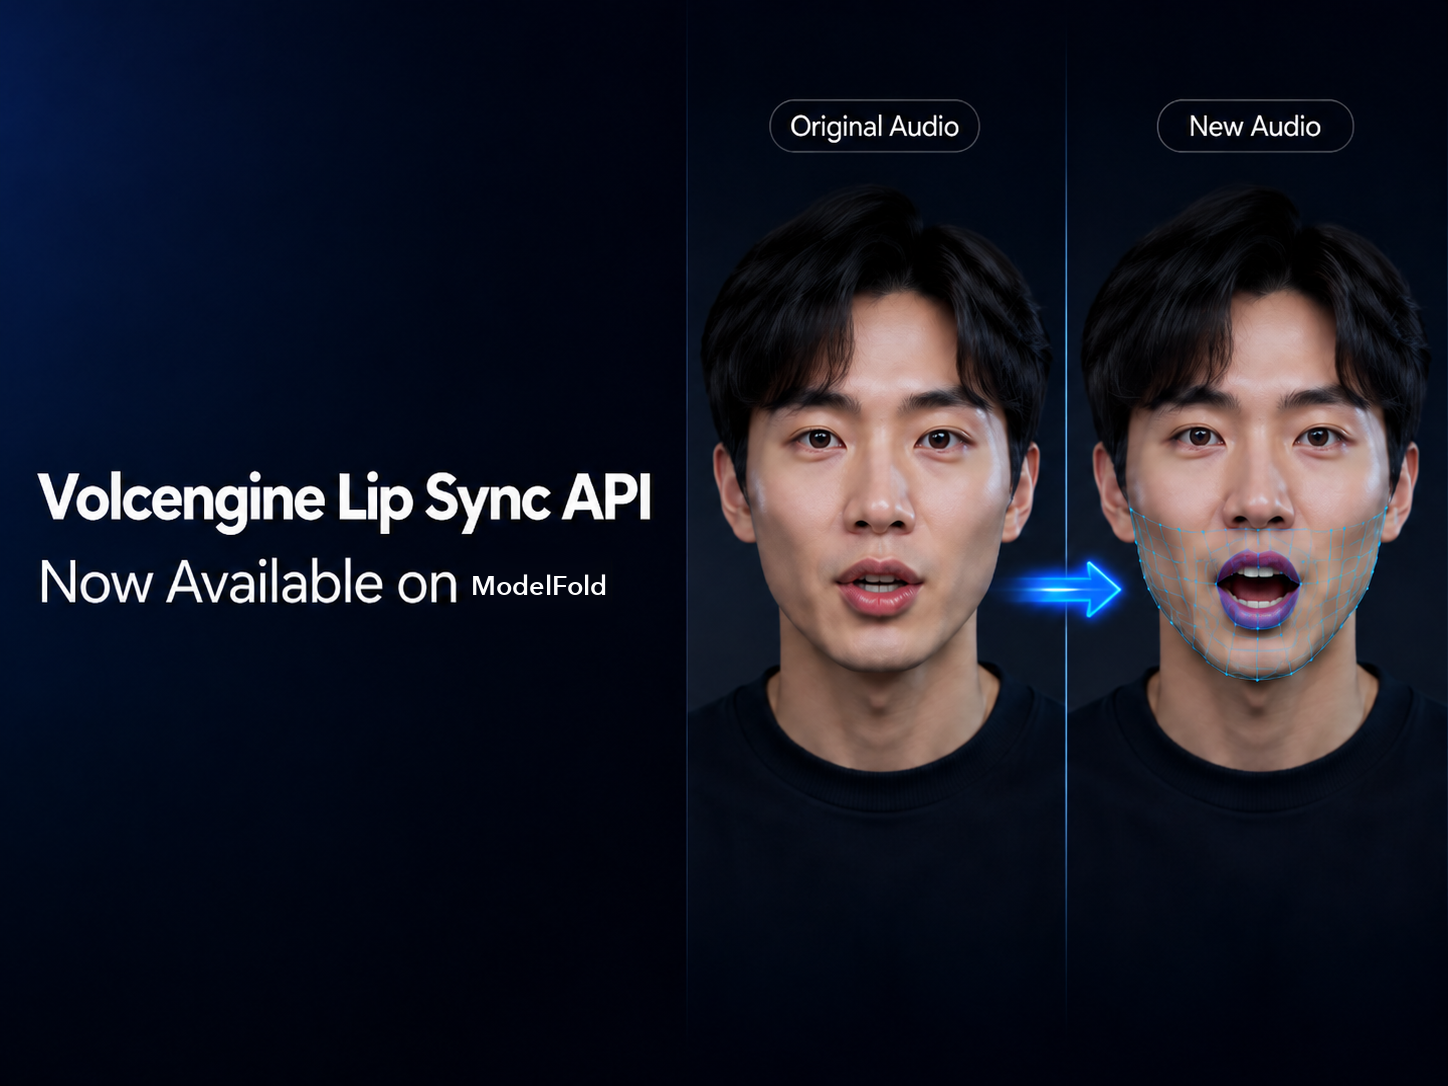
Volcengine Video-to-Video Lip Sync API で、AI による自然な口の同期と動画吹き替えを組み込めます。高精度な同期エンジンが大規模な多言語動画翻訳に対応します。ModelFold で利用できます。
料金: 長さにかかわらず 1 回あたり 60 クレジット。
ByteDance のほかの AI モデル
新着・人気の AI モデル
Volcengine Video-to-Video Lip Sync API
Integrate Volcengine Video-to-Video Lip Sync API for seamless AI lip sync video dubbing. High-accuracy mouth sync engine supporting multi-language video translation at scale. Available on ModelFold.
Models and variants
Select a model type for your task. The Playground uses the selected variant’s parameters and examples.
Video To Video Lip Sync
Model ID: volcengine/video-to-video-lip-sync. Check this variant’s required inputs and supported reference formats before submitting.
How to use
- 1
Select a variant
Choose a model type at the top of this page and review its rates and input requirements. Variants may support different reference media and outputs.
- 2
Prepare inputs
Fill in the Playground fields, supply any required image, video or audio, and adjust the available parameters. Examples demonstrate the workflow; use reference material you have permission to use.
- ✓
Review the result
Sign in, submit the task, and preview or download the result when it is ready. Task status is available in your account logs. For automation, use the API example below and the model documentation.
Parameters and pricing
The price table shows current ModelFold rates. Charges depend on the selected variant and its billing parameters. Size, resolution, duration, reference media or output count affect pricing only where specified by the model’s billing rules. Review the Playground estimate and your balance before submitting. Use the model ID and fields for your selected variant. Image, video and audio tasks have different inputs. For asynchronous tasks, wait for the status update rather than resubmitting while a result is pending.
Frequently asked questions
Are examples generated automatically?⌄
Examples are static demonstration assets. Browsing the page or switching variants does not generate content. Submitting a task calls the model and consumes credits at the displayed rates.
How should I choose parameters?⌄
Choose the model type first, then provide the fields and reference material its form requires. Do not assume every variant shares the same resolutions, durations or input limits.
How can I integrate it?⌄
Create an API key in your account, then follow the API example and model documentation. Keep the key on your server, outside browser code and public repositories.
| video to video lip sync | 60 クレジット 1 回あたり |
1 回ごとの固定料金で、動画の長さには左右されません。
curl https://ai.modelfold.online/v1/videos/generations \
  -H "Authorization: Bearer $MODELFOLD_API_KEY" \
  -H "Content-Type: application/json" \
  -d '{"model":"volcengine/video-to-video-lip-sync","prompt":"...","resolution":"720p","duration":5}'